OneFS Cluster Configuration Management

PowerScale OneFS is a distributed operating system, and keeping a cluster of up to 252 nodes in a consistent, well-managed state requires a clear division of responsibility across a set of foundational infrastructure components. Six of these underpin almost everything that happens in a cluster: gconfig, Tardis, MCP, the Job Engine, Persistent Queue (PQ), and sysctls.

Most of these components have been present across many OneFS generations, but they are frequently referenced in documentation without much explanation of exactly how they relate to each other.
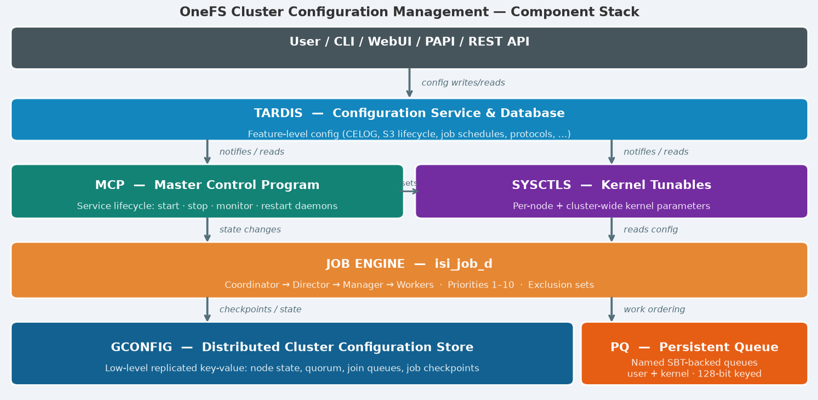
  1. At the bottom of the stack sits gconfig, OneFS’ distributed, replicated key-value configuration store. Every node in the cluster maintains a replica, and changes are propagated and committed cluster-wide before they take effect. gconfig holds raw cluster state: node membership, quorum data, join queues, distributed locks, and low-level service flags. It is the substrate everything else builds on — not because it is the most user-facing component, but because it is the one that has to survive partial cluster availability, node failures, and split-brain scenarios.

A good example of gconfig in direct use is the Automated Cluster Setup (ACS) system, which queues pending node serial numbers into gconfig under the gcfg_lazy_join.queued_nodes key. The Isi Lazy Join (ILJ) coordinator thread reads these entries directly from gconfig, attempts to join each node via the IPT discovery protocol, and then removes successfully joined entries from the queue. That entire flow (queue, match, join, dequeue) runs through gconfig without any higher-level abstraction layer in between. The same pattern applies to distributed lock coordination and quorum state management.

  1. Many newer OneFS features do not write to gconfig directly. Instead, they go through Tardis. But gconfig remains the authority for the lowest-level cluster mechanics (i.e. the things that have to work even when higher-level services have not yet started).

Tardis is the configuration service and database that sits above gconfig. Where gconfig is a raw key-value store accessed with low-level calls, Tardis presents a structured, service-oriented interface that higher-level components use to read and write their configuration. When a user submits a configuration change through the OneFS CLI, WebUI, or the platform API (pAPI), the pAPI handler writes the new configuration into Tardis, and Tardis notifies the relevant subscriber services.

The range of features that use Tardis is broad. CELOG uses it for event, alert, and channel configuration. S3 Lifecycle Management stores its bucket rules there. The Job Engine reads job type schedules, priorities, and impact policies from Tardis. NFS, SMB, and other protocol services store their configuration through pAPI into Tardis. In each case, the flow is the same: The pAPI handler receives the request, validates it, and writes the authoritative configuration into Tardis. The relevant daemon then picks up the change via its subscription to the Tardis notification stream.

  1. MCP, the Master Control Program, is OneFS’s service lifecycle manager — its equivalent of a system init daemon. Every userspace daemon that runs on a PowerScale node is started, monitored, and restarted by MCP. This includes isi_job_d, isi_papi_d, isi_stats_d, isi_nfs_d, and dozens of others. MCP watches both gconfig and Tardis for configuration changes that affect service state, and responds accordingly. If a feature is enabled that requires a new daemon, MCP starts it. If a daemon crashes, MCP restarts it, respecting any configured restart delay or retry limit.

MCP also enforces service dependencies. isi_job_d cannot start until gconfig and Tardis are both available. The platform API cannot start until lower-level services are ready. This sequencing is critical during node boot: the order in which services come online determines what is and is not available during each phase of startup. Getting that order wrong results in services that start without their dependencies satisfied, which leads to failures that are often confusing to diagnose.

From a troubleshooting perspective, MCP is often the first place to look when a daemon is unexpectedly absent or restarting. The ‘isi services’ CLI command displays MCP-managed service state across the cluster:

# isi services -a | grep -i job

isi_job_d   OneFS Job Engine   Enabled
  1. Sysctls are FreeBSD kernel tunables that control low-level OS and OneFS kernel module behavior. They sit at the boundary between userspace and the kernel — the place where configuration crosses from daemon-managed state into the kernel subsystems that handle networking, memory, I/O scheduling, and protocol processing. In OneFS, sysctls fall into two categories: those that are set per-node at boot and remain static until a reboot or explicit change, and those that are set dynamically by MCP-managed daemons in response to gconfig or Tardis changes.

A concrete example of the dynamic path: the NFS performance diagnostic statistics feature introduced in OneFS 9.15 exposes a slow operation logging threshold via a registry key (NfsSlowOpThresholdMs). That configuration is written through pAPI into Tardis, picked up by the NFS service, and applied as a kernel-level sysctl that the kernel NFS stack then enforces on every request. The user sees a single CLI command; behind it, the change traverses PAPI → Tardis → daemon → sysctl before it has any effect.

Cluster-wide sysctl propagation is coordinated through gconfig, ensuring that every node uses the same value. If needed, per-node overrides can be applied locally but not propagated. This makes sysctls the most ‘node-local’ of the six components since their state lives in the kernel of each individual node, rather than in a shared store.

  1. The OneFS Job Engine is the distributed background task execution framework responsible for dividing large cluster-wide operations (eg. FlexProtect, SmartPools, MultiScan, MediaScan, S3Lifecycle,etc) into work items and executing them in parallel across all nodes. It runs as a daemon (isi_job_d) on every node, is started and monitored by MCP, and operates as a four-level delegation hierarchy.
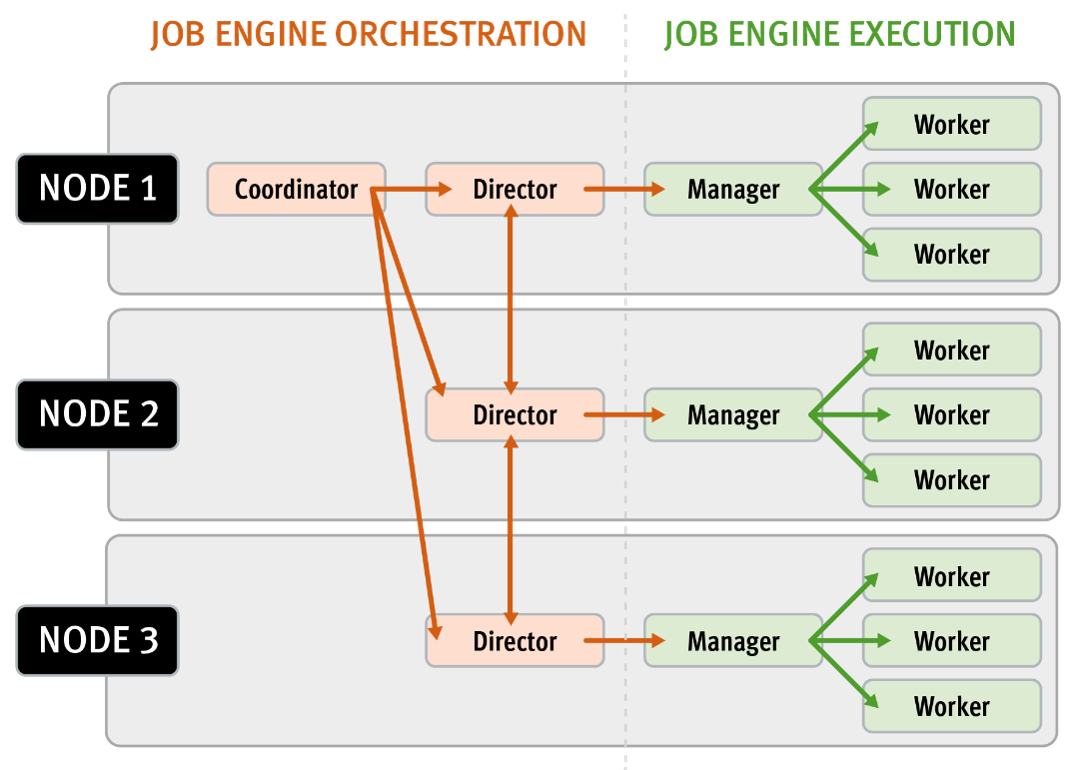
At the top of the hierarchy is the coordinator, which is a single process that can run on any node in the cluster. The coordinator is responsible for launching jobs, dividing work, controlling worker thread counts, and processing results as they come in. If the coordinator process dies, coordinator responsibility automatically moves to another node, with the election being handled via a gconfig distributed lock. The node currently acting as coordinator can be identified at any time:

# isi job status --verbose | grep Coordinator

Coordinator: node3 (lnn 3)

Below the coordinator, each node runs a director process that acts as a relay between the coordinator and the manager processes on that node. Each running job spawns its own manager on every participating node, and each manager controls a pool of worker threads that process the actual work items. This hierarchy means the coordinator never talks directly to individual workers, so instructions flow down through directors and managers, keeping the coordinator’s communication load manageable even on very large clusters.

The Job Engine reads its configuration (i.e. job type definitions, schedules, priorities, and impact policies) from Tardis. Job state and phase checkpoints are written to gconfig after each phase completes, which is what allows a paused or interrupted job to resume from where it left off even after a coordinator failover or node loss.

Scheduling is managed by the Job Engine’s own internal priority queue. Every job type is assigned a priority from 1 (highest) to 10 (lowest). Up to three jobs can run simultaneously, and the priority queue governs what happens when that limit is reached or when jobs share an exclusion set (a group of job types that cannot run concurrently because they contend for the same resources). When a higher-priority job needs to run and no slot is free, the lowest-priority running job is preempted: it is paused and returned to the back of the Job Engine priority queue, where it waits until it reaches the front again and a slot is available. For jobs of the same type and same priority, the one that was queued first runs first. Scheduling is also governed by cluster health: certain jobs are restricted based on device availability or degraded states. The FlexProtect and FlexProtectLIN jobs carry the highest default priority of 1, reflecting their role in reprotecting data:

# isi job types view FlexProtect

ID: FlexProtect

Description: Reprotects user data and data on unavailable devices.

Enabled: Yes

Policy: LOW

Schedule: when_source_modified

Priority: 1
  1. Persistent Queue (PQ) is a OneFS infrastructure service that provides ordered, durable queues for both user-mode and kernel-mode consumers, with each queue backed by an SBT (System B-Tree). This is the same B-tree structure that underpins other core OneFS metadata stores, allowing queue entries to survive process crashes, node reboots, and partial cluster failures. Entries are indexed by 128-bit B-tree keys and can carry an opaque data payload of up to approximately 8 KB each. Enqueuing an entry is transactional: either the entry is durably committed to the SBT or the operation fails cleanly. Contention avoidance between concurrent readers and writers is intentionally left to the caller. As such, PQ provides the durable storage primitive, not the concurrency policy.

PQ’s dual user-mode/kernel-mode accessibility is significant. Kernel-side components (eg. protocol handlers, the NFS layer, low-level filesystem operations) can enqueue work items directly without round-tripping through a userspace daemon. Userspace services read from the same queues. This makes PQ a natural integration point between kernel events and userspace processing pipelines, used wherever a kernel subsystem needs to hand off durable work to a userspace consumer without coupling them tightly in time.

A concrete example of PQ in practice is the trash directory queue, where each entry carries a root LIN (Logical Inode Number) and associated metadata. Over time, entries in this queue can become stale when the underlying LIN no longer exists in the filesystem, typically because the directory was already deleted or the data was cleaned up through another path. These orphaned entries illustrate a key property of the PQ design: entries are durable and persist until explicitly removed, and since contention avoidance is the caller’s responsibility, no background process automatically purges them.

PQ addresses this with two operational modes. In dump mode, it enumerates all entries in the trash_directory PQ, either printing all entries or only the stale ones. In cleanup mode, it removes every stale entry from the queue. All operations are logged to /var/log/isi_trash_pq_clean.log and via syslog.

A useful way to witness all six of these OneFS components interacting is to trace two common scenarios from start to finish.
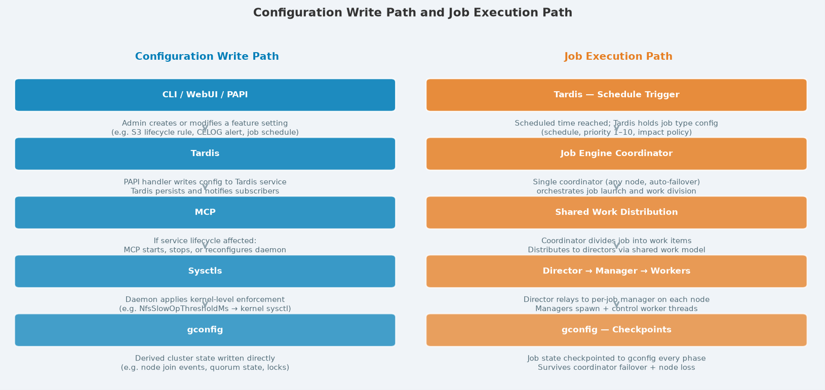
When a cluster admin makes a configuration change (eg. modifying the S3 lifecycle rules for a bucket) the platform API (pAPI) handler receives the request, validates it, and writes the new configuration into Tardis. Tardis notifies the relevant subscribers. If the change affects a service’s lifecycle (eg. enabling/disabling a feature), MCP responds by starting or stopping the appropriate daemon. If the change has a kernel-level enforcement requirement, such as an NFS tunable or a network stack parameter, the daemon applies it via a sysctl. Any derived cluster state (distributed flags, join queue entries) goes directly to gconfig.

On the job execution side, when a job such as S3Lifecycle’s scheduled timeslot arrives, Tardis surfaces that trigger to the Job Engine coordinator. The coordinator checks its internal job scheduling logic, and if fewer than three jobs are running and no exclusion set conflicts exist, the job starts immediately. If not, the coordinator holds the job until a slot opens. Once running, the coordinator divides the bucket tree into work items using the Job Engine’s shared work distribution model, distributing them through directors and managers to worker threads across all nodes. Phase completion is checkpointed to gconfig. If the coordinator node fails mid-job, a new coordinator is elected and reads the last checkpoint from gconfig to resume from the correct phase.

During a node boot, the kernel starts and loads its sysctls from ‘isi_sysctl.cfg’. MCP starts early and reads gconfig to determine service topology. MCP starts Tardis (the configuration service), then pAPI, then isi_job_d and all other feature daemons in dependency order. By the time the node is fully online, all six components are operational, each in its correct layer of the stack.

The division of labor between these components is deliberate. Gconfig handles the things that must work even in degraded cluster states. Tardis provides the structured configuration interface for features that assume the cluster is healthy. MCP ensures daemons are running and in the right state. The Job Engine distributes and executes background tasks across the cluster using its own internal shared work model, with checkpoints persisted to gconfig. PQ provides durable SBT-backed queue storage for other subsystems that require transactional, crash-safe queuing from user or kernel mode. Sysctls enforce configuration at the kernel level, where userspace cannot reach.

In summary, each layer does precisely what it needs to do, and, in concert, they cover the full spectrum from kernel tunables through distributed service lifecycle to long-running background task orchestration.

OneFS Configurable System Pool

The system pool is arguably the backbone of OneFS. It’s the dedicated diskpool that holds cluster-wide metadata, including the LIN (Logical Inode) tree.

Disk pools represent the smallest unit within the OneFS storage pools hierarchy.


OneFS provisioning works on the premise of dividing similar nodes’ drives into sets, or disk pools, with each pool representing a separate failure domain. In OneFS, a failure domain is the portion of a dataset that can be negatively impacted by a specific component failure. A disk pool comprises a group of drives spread across multiple compatible nodes, and a node usually has drives in multiple disk pools which share the same node boundaries. Since each piece of data or metadata is fully contained within a single disk pool, OneFS considers the disk pool as its failure domain.

Because the OneFS system pool handles the most read and write-intensive metadata operations on the cluster, it is acutely sensitive to disk latency. Any performance inefficiency in the system pool translates directly into metadata latency for every client on the cluster. In OneFS 9.15, administrators gain meaningful control over how the system pool is selected for the first time, through Capability 15648: Configurable System Pool.

Prior to OneFS 9.15, system pool selection followed a fixed rule, inherited from early OneFS design, which stipulated that the system pool must contain diskpools covering at least (N/2)+1 nodes, where N is the total node count. The algorithm prioritized SSD diskpools, but in mixed clusters where only a few nodes are all-flash and the majority are archive (HDD) nodes, covering half the cluster could force slower HDD diskpools into the system pool to satisfy the quorum threshold.

Fast SSD-backed reads and writes on the metadata path could become bottlenecked by slower HDD writes routed through the same system pool, producing metadata latency, lock timeouts, deadlocks, and periodic hangs. Manual resolution (i.e. removing the system flag from archive diskpools via gconfig and running a SmartPools job to migrate metadata back to SSD nodes) typically required both root access and a Dell support engagement.

However, in OneFS 9.15 and later releases, the system pool selection strategy is now configurable via the ‘isi storagepool settings’ CLI command set.

The following four strategies are available:

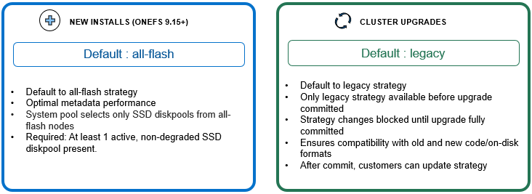
  • ‘All-flash’ strategy: Selects SSD diskpools from all-flash node pools only. Hybrid and archive node pools are excluded entirely. This is the maximum-performance configuration and the recommended strategy for any cluster that has all-flash nodes. It is the default for new OneFS 9.15 installs.
  • ‘Any-flash’ strategy: Picks all SSD diskpools including from hybrid nodes, while excluding the HDD diskpools within those hybrid pools. Offers more SSD capacity than all-flash at the cost of slightly variable latency, since hybrid-node SSDs share a chassis with HDDs.
  • ‘All’ strategy: Includes all non-degraded diskpools regardless of media type. Maximizes system pool capacity but does not prioritize performance. Closest in behavior to the pre-9.15 algorithm, without the N/2+1 quorum constraint.
  • ‘Legacy’ strategy: Preserves the original N/2+1 behavior with SSD diskpool prioritization. This is the default assigned to clusters upgrading to OneFS 9.15, ensuring no change to system pool composition during or after the upgrade.

The currently configured pool strategy can be viewed from the CLI as follows:

# isi storagepool settings view | grep -i pool

                System Pool Strategy: all-flash

Under the hood, this selected pool strategy is stored within gconfig under the ‘smartpools.storagepools.systempool_strategy’ key.

Architecturally, the system pool selection mechanism is event-driven, built atop the existing ‘isi_smartpools_d’ daemon. When a cluster admin changes the strategy via CLI, the new value is written to gconfig and a ‘needs_conform’ flag is set in the diskpool database. The ‘isi_smartpools_d’ daemon continuously monitors the diskpool DB for this flag. Upon detecting it, the daemon evaluates the available diskpools against the configured strategy, selects the appropriate set, and writes the result back into the diskpool DB, all without requiring any additional administrator action.

Behavior-wise, the default strategy differs between new OneFS 9.15 installs and upgrades:

For new clusters running OneFS 9.15 or later, the installer sets the default strategy to all-flash. The intent is that customers get optimal metadata performance immediately, without needing a tuning engagement to discover and configure the better strategy.

For clusters upgrading to OneFS 9.15, the strategy defaults to legacy. More importantly, the strategy is locked to legacy and cannot be changed until the upgrade fully commits. The reason is straightforward: during a non-disruptive upgrade, nodes running different OneFS versions coexist on the cluster. Older nodes would not be able to interpret a new pool layout generated by a strategy that didn’t exist in their version, which could result in panics or data unavailability. Once the upgrade commits and all nodes are on 9.15, the strategy can be freely changed.

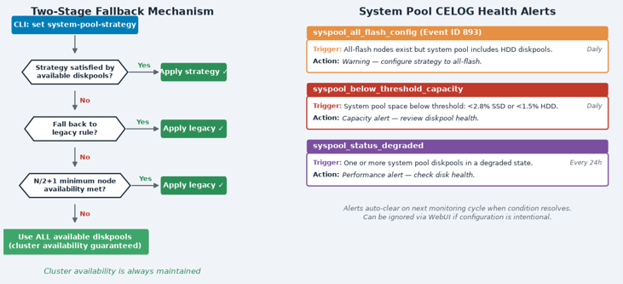
When a strategy is configured via CLI, a sanity check validates it against the current diskpool configuration. If the strategy cannot be satisfied, for example, when requesting all-flash on a cluster with no all-flash node pools, the CLI logs a warning to ‘isi_papi_d.log’, but allows the configuration to proceed. The system does not block the change, but it makes the incompatibility visible.

The ‘isi_smartpools_d’ daemon then performs the authoritative validation when it applies the strategy. If the configured strategy cannot be satisfied, a two-stage fallback ensures cluster availability is always maintained: First to legacy, and if legacy cannot meet its 50% node coverage threshold, to all available diskpools. Fallback events are logged to ‘/var/log/diskpools.log’ with specific messages indicating which strategy was attempted and what fallback was applied.

Pool strategy configuration is generally performed by using the following ‘isi storagepool’ CLI commands.

To view current system pool strategy:

# isi storagepool settings view

For example, to change the system pool strategy:

# isi storagepool settings modify --system-pool-strategy {all-flash | any-flash | all | legacy}

The ‘ISI_PRIV_SMARTPOOLS’ RBAC privilege is required for the new system pool strategy configuration CLI, while also providing access for related SmartPools operations. This privilege is granted by default for a cluster’s admin and root accounts, and no additional cluster license is required beyond the standard SmartPools/Storage Pools license.

Three new CELOG alerts in OneFS 9.15 provide proactive health visibility for the system pool:

Alert Details Message Frequency
syspool_all_flash_config Warns when cluster has all-flash nodes, but system pool strategy is not set to all-flash. “System pool is not configured optimally. Configure the system pool strategy to use all-flash.” 24H
syspool_below_threshold_capacity Alerts when system pool available space drops below configured threshold (typically, 2.8% for SSD and 1.5% for HDD). “System pool has available space below the required threshold.” 24H
syspool_status_degraded Notifies when system pool contains nodepools with degraded diskpools (with 2 or fewer nodes) “System pool has degraded nodepools: {nodepools_name}.” 12H

All three alerts can be acknowledged and ignored via the WebUI if the configuration is intentional, for example, if a cluster is deliberately running the ‘legacy’ strategy for compatibility reasons. Once the triggering condition resolves, the alert clears automatically on the next monitoring cycle.

For troubleshooting purposes, the following diagnostic CLI commands can be helpful.

To show current configured strategy:

# isi storagepool settings view

To modify pools with a selected strategy:

# isi storagepool settings modify --system-pool-strategy=<strategy>

With the ‘system-pool-strategy’ argument being one of:

--system-pool-strategy (all-flash | any-flash | all | legacy)]

To list all pools with media type:

# isi storagepool list

If needed, the gconfig value ‘manually_manage_system_flags’ can also be used to override automatic system pool selection by setting its value to ‘true’ from the default of ‘false’:

# isi_gconfig smartpools.diskpools.manually_manage_system_flags=true

One of the most common issues encountered is a strategy that looks correct in gconfig but isn’t being applied for some reason. To diagnose, first examine ‘/var/log/diskpools.log’ to identify whether a fallback was triggered, and then check ‘/var/log/isi_papi_d.log’ for a CLI-level incompatibility warning if the strategy was flagged at configuration time. Example warnings and error messages include the following:

Issue Logfile Message
Fallback warning /var/log/diskpools.log System pool strategy ‘any-flash’ is not supported by the available nodepools.
Unsupported strategy isi_papi_d.log Warning: Either there are no hybrid nodepools or the nodepools are degraded; falling back to legacy.


OneFS and OpenSSL 3.5

The OneFS 9.15 release enjoys a substantial security boost with the upgrade of OpenSSL from version 3.0.13 to 3.5.5. In tandem with this, the FIPS (Federal Information Processing Standards) provider module is also uplifted from 3.0.9 to 3.1.2. This upgrade is particularly beneficial for customers running PowerScale in a security-conscious or compliance-driven environment. This article walks through the what, why, and how of the upgrade.

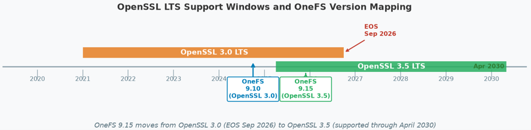
The OpenSSL 3.0 LTS stream reaches end-of-support in September 2026. Beyond this date it will receive no further security patches, CVE fixes, or maintenance updates from the upstream project. For a library that underpins virtually every cryptographic operation on a PowerScale cluster, from TLS handshakes to FIPS-compliant key management, remaining on an unsupported version would mean accumulated CVE exposure, static security scan failures, and potential compliance gaps in environments subject to government or industry mandates.

OpenSSL 3.5 is the next LTS release and is supported through April 2030, providing a further four years of patching headroom. The upgrade to 3.5.5 in OneFS 9.15 closes out ten CVEs carried in the 3.0 stream (one High severity, two Moderate, seven Low) and positions OneFS for the post-quantum cryptography work that will continue into the next release.

OpenSSL 3.x introduced a provider-based architecture that separates cryptographic algorithm implementations into loadable modules.

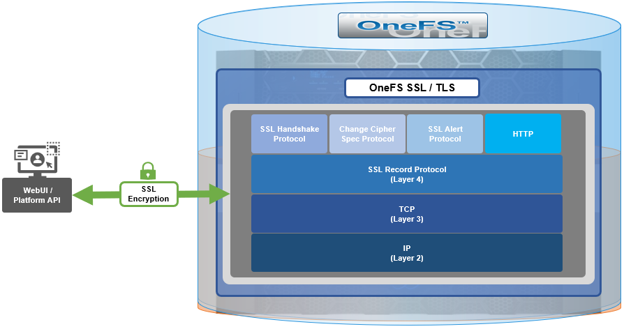
Architecturally, SSL comprises four fundamental layers:

SSL Component Description
Alert Reports issues.
Change cipher spec Implements negotiated crypto parameters.
Handshake Negotiates crypto parameters for SSL session. Can be used for many SSL/TCP connections.
Record Provides encryption and MAC.

These reside within the stack as follows:

The basic handshake process begins with a client requesting an HTTPS WebUI session to the cluster. OneFS then returns the SSL certificate and public key. The client creates a session key, encrypted with the public key it’s received from OneFS. At this point, the client only knows the session key and it sends this encrypted session key to the cluster, which decrypts it using the private key. Now, both the client and OneFS know the session key so the session, encrypted via the symmetric key, can be established. OneFS automatically defaults to the best supported version of SSL, based on the client request.

This model was established in OpenSSL 3.0 and carries forward to 3.5 without structural change, so the upgrade from OneFS 9.10’s OpenSSL 3.0.13 to 9.15’s 3.5.5 does not alter the fundamental architecture that administrators are already familiar with.

Four providers are defined, each scoped to a different class of algorithms:

Provider Details
Default Provider The general-purpose set of commonly used cryptographic algorithms.
Legacy Provider Deprecated or insecure algorithms such as MD2 and RC4, retained for backward compatibility.
Base Provider Key encoding and decoding operations; always loaded alongside the FIPS provider when FIPS mode is active.
FIPS Provider The FIPS 140-3 validated implementation. In OneFS 9.15 this is module version 3.1.2, holding CMVP certificate #4985.

Which providers are loaded at runtime is controlled by ‘/etc/ssl/openssl.cnf’, but in practice cluster admins never need to edit this file directly. OneFS manages provider selection through a higher-level abstraction: the FIPS mode toggle, exposed via the platform API (pAPI) or the gconfig switch. When FIPS mode is disabled, OneFS loads the Default and Legacy providers. When FIPS mode is enabled, it loads the FIPS and Base providers instead.

MCP (the Master Control Program) handles the mechanics of a FIPS mode change, dynamically rewriting the ‘/etc/ssl/fips_dynamic.cnf’ config file to reflect the new provider selection, and then restarting all affected daemons and services. This means a FIPS pAPI or gconfig toggle is applied cluster-wide without requiring manual intervention on individual nodes.

The SSL version jump from 3.0.13 to 3.5.5 is significant from a support and security perspective, but, for day-to-day cluster administration, the surface area of change is intentionally small. Unlike the update from SSL 1.0.2 to 3.0 in OneFS 9.10, which required substantive code changes across OneFS due to API differences, the 3.0 to 3.5 path is a within-major-version update. There are no new cryptographic providers, no new OneFS-specific protocols, and no new data structures introduced.

The one behavioral change worth noting explicitly is a default cipher update for the following OpenSSL command-line utilities:  ‘openssl req’, ‘openssl cms’, and ‘openssl smime’. In 3.5, these commands default to AES-256-CBC instead of the older 3DES (des-ede3-cbc). This is a command-line default only, and neither impacts the cipher negotiation behavior for any OneFS protocol or service, nor affects stored data or existing configurations.

On the FIPS side, the module version advances from 3.0.9 to 3.1.2, the highest FIPS 140-3 certified version available at the time the work was undertaken (CMVP certificate #4985). Existing FIPS mode settings are preserved across upgrade, and OneFS does not automatically enable or disable FIPS mode when nodes reboot into 9.15.

For reference, the following table includes the full set of OneFS subsystems with a direct OpenSSL or libcrypto dependency, grouped by functional area.

Functional Area Details
AIMA Local Provider, File Provider, LDAP, AD, Key Manager, Kerberos, mod_auth_isilon
Data Mobility Cloudpools, SyncIQ, Data Mover
Infrastructure Licensing, Upgrade, Patches, HealthCheck, Quota Notifier
Other PAPI, WebUI, Audit Syslog Forwarder, FreeBSD Userspace, CEE

Many other system components/utilities link to openssl / libcrypto (see output of ‘ldd …’)

Platforms Host Operating System Agent (HOSA), Power Tools Agent (PTA)
Protocols S3, SMB, NFS, HDFS/WebHDFS, RDR, Secure Channel, RAN, SSH/SFTP
Supportability isi_gather_info, Outgoing E-mail (Implicit TLS / port 465)

Upon upgrading to OneFS 9.15, OpenSSL 3.5 takes effect immediately when a node reboots into 9.15 or later, and the previous version is removed from the node at that point. As such, there is no deferred activation or option to retain the old library. Service continuity during the non-disruptive upgrade (NDU) window is maintained in the same way as any other OneFS component upgrade.

During a mixed-version upgrade window, nodes that have rebooted into OneFS 9.15 run binaries compiled against OpenSSL 3.5, while nodes still on an older build continue to use their compiled-in version. Interoperability between the two is maintained, with TLS handshakes between nodes at different OpenSSL versions completing successfully. SyncIQ and SmartSync replication to clusters running older OneFS versions are also unaffected. MCP correctly manages FIPS mode state on both upgraded and non-upgraded nodes throughout the transition.

After upgrade, the following CLI commands can be used to confirm the expected state, including:

To verify OpenSSL library version:

# openssl version

OpenSSL 3.5.5 27 Jan 2026 (Library: OpenSSL 3.5.5 27 Jan 2026)

Check FIPS mode status:

# isi security settings view | grep -i fips

FIPS Mode Enabled: Yes

List loaded providers (FIPS mode disabled):

# openssl list -providers

Providers:

  default

  legacy

Verify FIPS provider version (FIPS mode enabled):

# openssl list -providers -provider fips

Providers:

  fips

    version: 3.1.2

Test TLS connectivity to a specific endpoint:

# openssl s_client -connect <host>:<port>

Additionally, no new log files are created by the OpenSSL upgrade, so troubleshooting continues to use the standard OneFS log locations.

One of the motivations for incorporating OpenSSL3.5 into OneFS is that it provides the foundation for post-quantum cryptographic (PQC) algorithm support. OpenSSL 3.5 includes early implementations of the NIST-selected PQC algorithms (ML-KEM and ML-DSA among them) that will be needed as organizations begin preparing for the eventual deprecation of RSA and elliptic-curve cryptography in the face of quantum computing advances.

No PQC algorithms are exposed to PowerScale cluster users in OneFS 9.15, since the OpenSSL 3.5 upgrade is the enabling step, not the delivery. Integration of PQC into specific OneFS protocol and service layers is planned for a future release.

The OpenSSL 3.5 upgrade in OneFS 9.15 is primarily a forward-looking security and supportability move. Remaining on OpenSSL 3.0 past September 2026 would mean accumulating unpatched CVEs, failing static security scans, and losing access to maintenance fixes from the upstream project. The 3.5 LTS stream extends support coverage to April 2030 and closes ten CVEs already in the 3.0 stream.

For cluster admins, the operational footprint of this change is minimal. The provider architecture is unchanged, FIPS mode is preserved across upgrade, no new configuration is required, and the upgrade proceeds through the normal NDU path. The one behavioral change, the AES-256-CBC default for openssl command-line utilities, is narrow in scope and unlikely to affect most environments.

OneFS pNFS and NIC Trunking

The previous two articles in this series examined what Parallel NFS (pNFS) is, how it is implemented in OneFS 9.15, and how to enable, configure, and manage pNFS on a PowerScale cluster. The recurring theme was parallelism on the cluster side: By separating the metadata path from the data path, pNFS lets a single NFS client read and write file data directly and concurrently across many nodes, rather than funneling everything through the one node behind the mount IP. Every node in the SmartConnect pool can act as a Metadata Server (MDS) or a Data Server (DS), so the cluster presents a genuinely parallel data path.

However, there is a second half to that equation, and it resides with the pNFS client. While the data path can be opened across many nodes, if a Linux client sends every one of those data connections out of a single network interface, the client itself becomes the bottleneck.

In this final article of the series, we look at client-side NIC trunking, a lightweight, fully reversible technique that spreads a single pNFS mount’s data-server connections across two client NICs so that one mount can drive the aggregate bandwidth of both.

With pNFS flex-files, defined in RFC 8435 and carried over NFSv4.1 or NFSv4.2, a file system’s metadata path is separated from its data path. In a flex-files deployment, the PowerScale cluster fills two roles at once:

Role Description
Metadata Server (MDS) The IP address you mount. It handles namespace operations and issues data layouts to the client through the LAYOUTGET operation.
Data Server (DS) The addresses the client reads and writes file data to directly. Every node in the network pool can act as a DS, so DS addresses span the entire pool range.

When the client performs I/O, the MDS returns a flex-files layout listing the DS addresses for the data, and the client opens transport connections directly to those addresses. The problem is what happens next on the client. By default, Linux resolves all of those DS addresses to a single egress interface (the route with the lowest metric wins), so every data connection leaves through one NIC. A client with two NICs attached to the same PowerScale data network therefore uses only half of its available bandwidth, while the second NIC sits idle.

The technique pins half of the pool’s addresses to each NIC using host-specific (/32) routes. Data-server connections then fan out across both interfaces, so a single mount can drive the aggregate bandwidth of both NICs. The approach works identically for RDMA (RoCE/InfiniBand) and TCP; the RDMA-only steps are called out where they apply. Importantly, all configuration is performed on the Linux client, and the cluster requires no change beyond having NFS over RDMA and pNFS flex-files enabled on the export.

Consider a Linux client with two NICs sitting on separate subnets, each with its own gateway to a PowerScale cluster’s front-end network. Host routes split the pool so that, in our example, IP addresses .81 to .100 egress NIC 1 and .101 to .120 egress NIC 2. Whichever PowerScale cluster node answers the mount request acts as the MDS, and the flex-files layouts it returns still reference DS addresses drawn from across the whole pool, so both NICs are exercised once the routes are split evenly.

One caveat is worth noting up front: Split the data pool you actually mount through, not the management pool, and not a different data pool. OneFS returns roughly one DS address per node drawn from the pool your mount uses. If the cluster has several data pools on different ranges, mounting through one pool returns only that pool’s DS addresses, so splitting a different range accomplishes nothing.

Prerequisites

Before making any changes, confirm that all the following client, cluster, and networking prerequisites are met.

On the Linux client

Client Prerequisite Details
Operating system A recent enterprise Linux distribution with NFS/RDMA, pNFS flex-files, and nconnect support, for example RHEL 8.x/9.x, Ubuntu 20.04+, or SLES 15 SP3+.
Installed packages The ‘rdma-core’ and ‘nfs-utils’ packages installed.
Network interfaces Two client NICs, each with its own IP address and a working route to the cluster data subnet.
Access control Root (or sudo) access.
RDMA-only configuration Confirm each NIC’s RDMA device mapping with rdma link show (for example, mlx5_0 maps to eth0).

On the PowerScale cluster:

Cluster Prerequisite Details
OneFS version OneFS 9.15 or later.
Network interfaces RDMA-capable front-end interfaces.
NFS configuration NFS over RDMA enabled and pNFS flex-files enabled on the export.

Verify that NFS over RDMA is enabled on the cluster:

# isi nfs settings global view | grep -i rdma

On the network:

Network Prerequisite Details
Transport A RoCEv2 fabric with lossless Ethernet (PFC/ECN) configured end-to-end.
Routing One subnet per client NIC is recommended for clean routing, with a reachable gateway on each NIC’s subnet toward the cluster pool..

The commands throughout this article use the example values below. Substitute your own environment’s IP addresses and paths consistently, as appropriate.

The pool is split in half: For example, .81 to .100 via NIC 1, and .101 to .120 via NIC 2.

Item Value Notes
Cluster data subnet 192.168.100.0/24 Where the NFS pool lives
Network pool range 192.168.100.81 to .120  (40 IPs) Any one IP is the mount target; all are potential DS IPs
NIC 1 eth0, 10.10.1.11, gw 10.10.1.254, mlx5_0 First client NIC
NIC 2 eth1, 10.10.2.11, gw 10.10.2.254, mlx5_1 Second client NIC
Export path /ifs/data NFS export on the cluster
Mount point /mnt/pscale Local directory on the client

The following NFS mount options are used throughout:

Option Value Purpose
proto rdma Use RDMA transport (use tcp for the TCP variant)
port 20049 Standard NFS-over-RDMA port
vers 4.1 NFSv4.1, required for pNFS flex-files
rsize / wsize 1048576 1 MB I/O buffers (a good default for RDMA)
nconnect 4 Parallel connections per DS IP; start at 4 and raise only if a single DS connection bottlenecks

Deployment procedure

The PowerScale pNFS NIC trunking deployment procedure comprises eight steps, of which all are performed on the Linux client, except Step 1, which queries the cluster.

The recommended path is to validate first with temporary routes (Step 3, Option A), confirm the split is working (Steps 4 through 8), and only then make the routes permanent (Step 3, Option B). Specifically:

Step 1 – Confirm the cluster pool

On the cluster, examine the SmartConnect static network pool to obtain the exact IP range and gateway that the client will route across its two NICs:

# isi network pools list

# isi network subnets list

You will mount one address from this range (or the pool’s SmartConnect DNS name, which resolves to one of them) and route the entire range across your two NICs. Use the NFS data pool, not the management pool. A management or pool0 address may answer ping and even accept a TCP connection on port 2049, but mounts through it hang and never produce data layouts.

Step 2 – Back up the current network configuration

Before changing anything on the Linux pNFS client, capture the runtime routing state so you can restore it (all distributions):

mkdir -p /root/net-backup-$(date +%F)

ip route show > /root/net-backup-$(date +%F)/routes.txt

ip rule show  > /root/net-backup-$(date +%F)/rules.txt

Also back up the persistent network configuration for your distribution. This is only required if using Option B (permanent routes) in Step 3. For NetworkManager (RHEL, Rocky, SLES), profiles live in /etc/NetworkManager/system-connections/ (keyfile) or /etc/sysconfig/network-scripts/ (ifcfg); for netplan (Ubuntu), back up /etc/netplan:

# Ubuntu / netplan example

cp -a /etc/netplan /root/net-backup-$(date +%F)/

Step 3 – Add the split routes

Add a host-specific (/32) route for every pool address, sending half to each NIC. There are two ways to accomplish this, so select one of the following methods as appropriate:

Option A: Temporary Configuration (runtime only, for testing).

These routes take effect immediately but to not persist a reboot, which makes them ideal for validating the configuration before committing. Run as root on the Linux client:

# .81–.100 via NIC 1

for id in {81..100}; do

  ip route replace 192.168.100.$id via 10.10.1.254 dev eth0 src 10.10.1.11

done

# .101–.120 via NIC 2

for id in {101..120}; do

  ip route replace 192.168.100.$id via 10.10.2.254 dev eth1 src 10.10.2.11

done

ip route flush cache

The ‘src’ attribute above pins the connection’s source address to the egress NIC. It is required for RDMA (the RoCE source GID must belong to the egress device) and keeps the path symmetrical. The commands are safe to re-run because the ‘ip route replace’ command is idempotent,.

Option B: Permanent Configuration.

Store the routes declaratively so the network stack reapplies them on boot or NIC bounce. Do not combine methods for the same addresses.

NetworkManager (RHEL, Rocky, SLES): add the routes with the ‘nmcli’ CLI command, using the connection name (from ‘nmcli connection show’), which often differs from the device name:

nmcli connection show    # note the NAME column (may differ from DEVICE)

# NIC 1 connection

for id in {81..100}; do

  nmcli connection modify eth0 \
+ipv4.routes "192.168.100.$id/32 10.10.1.254 src=10.10.1.11"

done

# NIC 2 connection (name may be e.g. "Wired connection 1")

for id in {101..120}; do

  nmcli connection modify "Wired connection 1" \
+ipv4.routes "192.168.100.$id/32 10.10.2.254 src=10.10.2.11"

done

nmcli connection up eth0

nmcli connection up "Wired connection 1"

Note that the ‘nmcli connection up’ command briefly bounces the interface and drops any SSH session running over that NIC. Run the connection activation from the console/BMC, or detached (for example, wrap it in ‘nohup … &’), and do not chain the two commands with ‘&&’ over a live SSH session on the first NIC.

For Ubuntu linux using the ‘netplan’ CLI command, add routes under each interface in the netplan YAML, then run the ‘sudo netplan apply’ command. A route placed under an interface egresses that interface, and uses its IP as the source automatically, so no explicit ‘src’ is required. Validate with the ‘sudo netplan generate’ command before applying:

network:

  version: 2

  ethernets:

    eth0:

      routes:

        - to: 192.168.100.81/32

          via: 10.10.1.254

        # ... one entry per .81–.100

    eth1:

      routes:

        - to: 192.168.100.101/32

          via: 10.10.2.254

        # ... one entry per .101–.120

An alternative, Linux OS-agnostic option uses the ‘systemd oneshot’ service. For mixed client fleets, or when a single approach across all hosts is preferred, this small oneshot service replays the ‘Option A’ commands at boot. It is the most transparent method, and the safest to apply remotely, because it never reconfigures a NIC’s address and so never bounces a link:

# /usr/local/sbin/nfs-trunk-routes.sh

#!/bin/bash

set -e

for id in {81..100}; do

  ip route replace 192.168.100.$id via 10.10.1.254 dev eth0 src 10.10.1.11

done

for id in {101..120}; do

  ip route replace 192.168.100.$id via 10.10.2.254 dev eth1 src 10.10.2.11

done

ip route flush cache


# /etc/systemd/system/nfs-trunk-routes.service

[Unit]

Description=Split NFS pool routes for NIC trunking

After=network-online.target

Wants=network-online.target

[Service]

Type=oneshot

RemainAfterExit=yes

ExecStart=/usr/local/sbin/nfs-trunk-routes.sh

[Install]

WantedBy=multi-user.target


chmod +x /usr/local/sbin/nfs-trunk-routes.sh

systemctl daemon-reload

systemctl enable --now nfs-trunk-routes.service

systemctl status nfs-trunk-routes.service --no-pager  # expect: active (exited)

An ‘on-link pool’ (no gateway) is a special case. If the cluster pool is in the same subnet as the client NICs, shown by the ‘ip route show’ CLI command as a proto kernel scope link route with no via, omit the gateway (for example, ‘ip route replace 192.168.100.81 dev eth0 src 10.10.1.11’, or, in netplan, use ‘scope: link’ with no via). When the pool is reached through a router, keep the gateway.

Step 4 – Verify the split

On the client, confirm that the boundary addresses resolve to the expected interfaces:

ip route get 192.168.100.81    # expect: dev eth0  src 10.10.1.11

ip route get 192.168.100.100   # expect: dev eth0  src 10.10.1.11

ip route get 192.168.100.101   # expect: dev eth1  src 10.10.2.11

ip route get 192.168.100.120   # expect: dev eth1  src 10.10.2.11

Or check the whole pool at once:

for id in {81..120}; do ip route get 192.168.100.$id | head -1; done

Using this example configuration, addresses .81 to .100 should all show eth0, and .101 to .120 should all show eth1.

Step 5 – Connectivity check (optional)

A quick reachability check before mounting. Skip it if you prefer to go straight to Step 6, since the mount plus the verification in Steps 7 and 8 is the definitive end-to-end test:

# RDMA only: both devices should be ACTIVE / LINK_UP

rdma link show

# reach one IP from each half over its intended NIC

ping -c2 -I eth0 192.168.100.81      # path via NIC 1

ping -c2 -I eth1 192.168.100.101     # path via NIC 2

A ping failure on one NIC means that path is down, so check link state, switch/VLAN configuration, and gateway reachability (for example, ‘arping -I eth1 10.10.2.254’).

Step 6 – Mount

Mount one pool address as the MDS, using nconnect to set the number of connections opened per DS address. For RDMA:

mount -v -o proto=rdma,port=20049,vers=4.1,rsize=1048576,wsize=1048576,nconnect=4 \
192.168.100.81:/ifs/data /mnt/pscale/

For the TCP variant, replace ‘proto=rdma,port=20049’ with ‘proto=tcp’. The mount confirms the source address it selected, and the reported ‘clientaddr’ should match your NIC 1 IP (10.10.1.11). Immediately after mounting, and before any I/O, only the MDS address appears in the transport table, which is expected, because DS connections are created once I/O triggers LAYOUTGET.

To remount automatically on boot, add an ‘fstab’ entry on the client (_netdev’ defers the mount until the network is up):

192.168.100.81:/ifs/data  /mnt/pscale  nfs4  \
proto=rdma,port=20049,vers=4.1,rsize=1048576,wsize=1048576,nconnect=4,_netdev  0  0

Step 7 – Verify trunking: transport connections

Generate a small amount of I/O (for example, a ‘find’, or a short ‘fio’ or ‘dd’ job) to trigger layout retrieval, then count the transport connections per address:

grep -h 'addr:' /sys/kernel/debug/sunrpc/rpc_xprt/*/info \

  | awk '{print $2}' | sort -t. -k4 -n | uniq -c

Healthy trunking shows every participating address with ‘nconnect’ (here, 4) connections: the MDS plus DS addresses from both halves of the pool:

  4 192.168.100.81     <- MDS (NIC 1 range)

  4 192.168.100.90     <- DS  (NIC 1 range)

  4 192.168.100.101    <- DS  (NIC 2 range)

  4 192.168.100.118    <- DS  (NIC 2 range)

  ...

If only .81 to .100 appear, the NIC 2 routes are wrong, so recheck Step 4. Entries for the cluster management address (port 2049) and the local rpcbind socket are unrelated to data I/O and can be ignored.

Step 8 – Verify trunking: RDMA queue pairs (RDMA only)

For RDMA configurations, confirm that queue pairs (QPs) exist on both RDMA devices:

rdma resource show qp link mlx5_0    # NIC 1

rdma resource show qp link mlx5_1    # NIC 2

Both devices must return QPs, and each should carry roughly half of the total. For a 40-address pool with nconnect=4, that is about 20 × 4 = ~80 QPs per device. QPs on only one device mean all traffic is on one NIC, so recheck the routes for the other half. If you validated with temporary routes (Option A) and everything checks out, return to Step 3, Option B to make the routes permanent.

Rollback and restore

To return to the original configuration, roll back using the same method you applied (replace the backup date with the date of your Step 2 backup directory).

Temporary routes (Option A, all distributions): delete the host routes, or simply reboot:

for id in {81..120}; do ip route del 192.168.100.$id; done

ip route flush cache

NetworkManager: remove exactly the routes you added, using -ipv4.routes:

# NIC 1 connection

for id in {81..100}; do

  nmcli connection modify eth0 \
-ipv4.routes "192.168.100.$id/32 10.10.1.254 src=10.10.1.11"

done

# NIC 2 connection (use the same NAME you used to add the routes)

for id in {101..120}; do

  nmcli connection modify "Wired connection 1" \
-ipv4.routes "192.168.100.$id/32 10.10.2.254 src=10.10.2.11"

done

nmcli connection reload

nmcli connection up eth0

nmcli connection up "Wired connection 1"

Do not rely on restoring the keyfile backup alone: If a NIC had no saved profile when you backed up, Option B created a new keyfile for it, and a plain cp -a restore never deletes that new file, so those routes survive the rollback. Use the -ipv4.routes method above, then verify none remain with ‘ip route show | grep /32’.

Netplan (Ubuntu): Restore the backed-up netplan, then apply. If you added a separate file, delete it first (the backup will not contain it):

rm -f /etc/netplan/90-pnfs-trunking.yaml   # only if you created a separate file

cp -a /root/net-backup-YYYY-MM-DD/netplan/* /etc/netplan/

sudo netplan apply


Systemd service (all distributions): Disable the unit, remove its files, then clear the live routes (or reboot):

systemctl disable --now nfs-trunk-routes.service

rm -f /etc/systemd/system/nfs-trunk-routes.service \

      /usr/local/sbin/nfs-trunk-routes.sh

systemctl daemon-reload

for id in {81..120}; do ip route del 192.168.100.$id; done

ip route flush cache

Troubleshooting

Symptom Likely cause Resolution
Ping or mount hangs on one NIC’s path No working path via that NIC’s gateway Check link, switch/VLAN, and gateway (arping -I eth1 10.10.2.254)
Mount hangs though ping and port are reachable Mounting the wrong pool (management, not data) Confirm the IP is in the NFS data pool (isi network pools list); mount a data-pool IP
Only NIC 1 addresses in the transport table NIC 2 host routes missing or wrong Recheck ip route get 192.168.100.101
No QPs on mlx5_1 RDMA device not mapped to NIC 2 rdma link show; confirm device-to-netdev mapping
Transport table shows only the MDS IP after I/O pNFS flex-files inactive, or no real I/O performed Confirm flex-files is enabled on the export; perform real reads/writes
ip route get shows the wrong NIC Route cache stale ip route flush cache
SSH session drops during Option B apply/rollback nmcli connection up bounced the NIC carrying your session Run the activation detached (nohup … &) or from console/BMC
Routes still present after Option B rollback cp -a keyfile restore did not delete an NM-created profile Use the -ipv4.routes rollback method; verify with ip route show
ip route replace permission error Not root Use sudo

The following recommended practices can help ensure a reliable, maintainable NIC-trunking deployment, regardless of the persistence method or transport (RDMA or TCP):

  • Gateways: reuse the existing gateway each NIC already uses for the cluster subnet (from ip route show) rather than creating new ones.
  • Source pinning: the src attribute pins the source address to the egress NIC. It is required for RDMA and keeps the path symmetric.
  • Uneven pools: adjust the pool ranges so roughly half of the addresses go to each NIC. The split need not be exactly even.
  • nconnect: start at nconnect=4 and raise it only if a single DS connection becomes a bottleneck.
  • Verify before permanence: validate with temporary routes, confirm with the checks in Steps 7 and 8, and only then make the configuration permanent. Always keep a tested rollback option.

So, in summary, client-side NIC trunking is an efficient, fully reversible way to unlock the aggregate bandwidth of two client interfaces for pNFS flex-files on a PowerScale cluster running OneFS 9.15 or later. Because the technique relies only on host-specific routes and an nconnect mount, it requires no cluster-side change and applies equally to RDMA and TCP. Following the procedure above (confirm the correct data pool, back up first, split the routes, verify with the transport and queue-pair checks, and persist with a tested rollback in place) delivers a single mount that drives data traffic across both NICs.

OneFS MetadataIQ Automatic Directory Rename Propagation

Since OneFS 9.10, MetadataIQ has provided PowerScale clusters with a global metadata namespace, by exporting file system metadata to an off-cluster Elasticsearch database. The ability to index and query metadata across geo-distributed clusters, without resorting to time-consuming tree walks, has proven invaluable for data discovery, lifecycle management, and increasingly for AI-driven workflows such as intelligent chunking and retrieval-augmented generation (RAG).

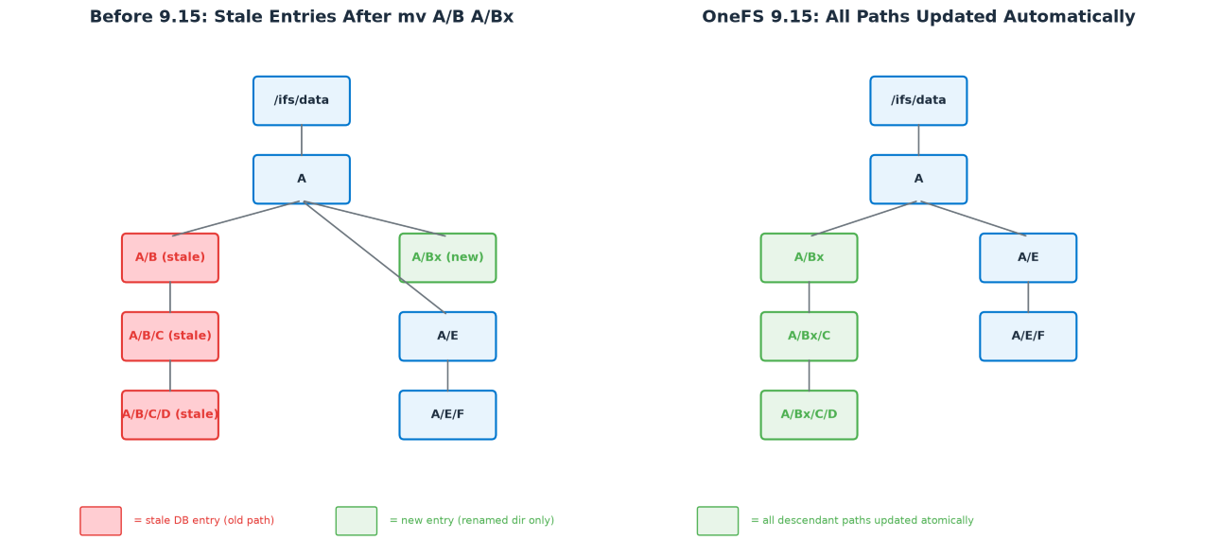
However, in OneFS 9.14 and earlier, when a directory was renamed on the cluster, MetadataIQ dutifully recorded the new directory entry in Elasticsearch, but every child path beneath that directory remained indexed under the old prefix. This resulted in stale entries: the database reported the files living under /ifs/data/A/B/C, but the file system had them under /ifs/data/A/Bx/C. Until the release of OneFS 9.15, the only remedy was a full resync — a brute-force re-indexing of the entire dataset that is neither performant nor automation-friendly.

The new OneFS 9.15 releases addresses this MetadataIQ shortcoming with automatic directory rename propagation. Specifically, when a directory rename is detected, the system now tracks both the old and new paths and runs a dedicated rename phase that updates all descendant entries in the Elasticsearch index, eliminating stale data without a full resync. Additionally, the schema encoding for hardlinks has been redesigned to remove path sensitivity entirely.

To understand the solution, it helps to be clear about the problem. MetadataIQ’s Elasticsearch index uses a primary key (_id) for each document. In releases prior to 9.15, this ‘_id’ was encoded as a combination of the file’s LIN (logical inode number) and a hash of its full path: <LIN>#<path_hash>.

This encoding has two consequences when a parent directory is renamed:

  • Every child entry in the database retains its old path. A directory rename from /ifs/data/projects to /ifs/data/projects_2026 leaves every file and subdirectory under it still indexed with the /ifs/data/projects prefix. The database and the file system disagree, and queries return incorrect results.
  • For hardlinks, the path_hash component of the _id changes when a parent is renamed, even though the file itself has not changed. This creates duplicate or orphaned entries in the index.

Pre-OneFS 9.15 this required an expensive resync, effectively re-indexing the full dataset.

However, to avoid this overhead, the directory rename feature in OneFS 9.15 operates within MetadataIQ’s existing transfer agent (‘isi_metadataiq_transfer’), adding a post-processing rename phase that runs after the normal changelist transfer is complete. As such, the 9.15 workflow has two distinct phases:

Phase 1: Primary Processing

During normal MetadataIQ processing, the transfer agent iterates through the changelist entries and pushes them to the Elasticsearch database. When a directory rename event is detected, the following occurs:

  • The changelist entry is pushed to the database as usual, with the old path and path depth preserved.
  • The new directory path is recorded in a special rename_path field on the renamed directory’s document in Elasticsearch.
  • Metadata fields such as timestamp, disk pool, and node pool are updated to reflect the current file system state.

At this stage, the children of the renamed directory still have their old paths in the database. The rename_path field is a breadcrumb that tells Phase 2 which directories have pending renames.

Phase 2: Rename (Post-processing)

After all primary changelist processing is complete, the transfer agent enters the rename phase. This is where the descendant path updates happen:

  • The script queries Elasticsearch for all documents that have a non-empty rename_path field — these are the directories with pending renames.
  • For each rename candidate, the script identifies all descendant entries whose path begins with the old directory prefix. These are processed in descending order by path depth, ensuring that deeply nested renames are handled correctly before their parents.
  • The actual path update is performed atomically using an Elasticsearch Painless script execution. A single Painless script replaces the old path prefix with the new directory path and recomputes associated metadata for all descendants. This atomic update includes:

–  Path depth: adjusted by calculating the depth difference between the new and old paths.

–  Snapshot generation number: updated atomically so that parent-level renames can skip entries already modified by a child-level rename.

–  Other metadata fields: all relevant metadata is refreshed for every descendant entry.

  • Once the root rename document and all its descendants are updated, the rename_path field is cleared, marking that rename as complete.
  • This process iterates until all pending renames have been resolved.

Above, Phase 1 (blue) records rename candidates during normal changelist processing, while phase 2 (green) iterates through candidates and atomically updates all descendant paths.

Note that the descendant prefix search in Elasticsearch requires the ‘allow_expensive_queries’ setting to be enabled, which it is by default. This setting should not be disabled on MetadataIQ’s Elasticsearch instance.

The MetadataIQ transfer agent uses batched, checkpointed processing throughout both phases. An interrupted transfer resumes from the last recorded checkpoint rather than restarting from the beginning. The various stages of the transfer workflow are as follows:

Stage Description
Fetch batch Fetch changelist entries batchwise from the PAPI server (maximum 2,048 entries per fetch)
Detect rename Detect directory rename events within the batch
Record rename_path Record the new path in the rename_path field; preserve the old path and path depth
Checkpoint Refresh object metadata, update ‘tail_cookie’, and record a checkpoint at batch end
Iterate candidates In the rename phase, iterate over each recorded directory rename candidate
Find descendants Identify descendants by old path prefix, processed in descending depth order
Update child paths Replace the old prefix with the new directory path and update child metadata
Reconcile Clear the rename_path field, marking the subtree as fully reconciled
Failure exit On crash or ElasticSearch connection failure, exit and resume from the last checkpoint

If the transfer script exits during the rename phase, for example, in the event of a node failover, service restart, or a network interruption, the ‘rename_path’ fields in Elasticsearch remain set on any unprocessed rename candidates. When the transfer agent is next invoked, it detects these pending rename entries, skips the primary processing phase entirely, and proceeds directly to the rename phase to complete the outstanding work. No manual intervention is required. This is a significant improvement over the old full-resync approach, where an interrupted resync would simply need to be restarted from the beginning.

The second component of the directory rename feature addresses the hardlink problem at the schema level. In pre-9.15 releases, the Elasticsearch document ‘_id’ is encoded as ‘<LIN>#<path_hash>’. Since a hardlink is an additional directory entry pointing to the same inode, renaming a parent directory changes the ‘path_hash’ for every hardlink entry beneath it, creating duplicates or orphans in the index.

In OneFS 9.15, the ‘_id’ encoding for hardlinks is changed to use the parent LIN and filename rather than a full path hash. Because the filename itself does not change when a parent directory is renamed, hardlink entries are no longer sensitive to parent path changes. This eliminates an entire class of stale-entry scenarios.

The OneFS 9.14 and earlier encoding includes a hash of the full path, which changes when any ancestor is renamed. Conversely, the 9.15 encoding uses only the filename, making hardlinks immune to parent renames.

Architecturally, the rename phase is built directly into the existing MetadataIQ transfer agent. No new daemons, services, or ports are introduced. The transfer agent (‘isi_metadataiq_transfer’) already handles the mechanics of reading changelist entries, batching them, and uploading them to Elasticsearch. The rename phase simply adds a post-processing step after the draining loop completes.

There are two paths into the rename logic:

Path Details
Normal path After the primary processing phase completes and all changelist entries have been drained to Elasticsearch, the rename phase is triggered automatically.
Recovery path If the transfer script was interrupted during a previous rename phase (leaving unprocessed rename_path entries in Elasticsearch), the next invocation skips primary processing and goes directly to the rename phase.

No separate installation or configuration is required for the directory rename feature. It is built into OneFS 9.15 and follows the same installation, configuration, and scheduling as the existing MetadataIQ capability. If MetadataIQ is already configured and running on a pre-9.15 cluster, upgrading to 9.15 enables directory rename propagation automatically after the upgrade commit and subsequent resync.

The existing MetadataIQ CLI commands remain unchanged:

# isi metadataiq settings view

# isi metadataiq settings modify --schedule "every day every 5 minutes"

# isi metadataiq resync

When it comes to upgrading OneFS and MetadataIQ, the directory rename feature introduces a change to the ‘_id encoding’ in the main Elasticsearch index in order to eliminate the path dependency for hardlinks. This encoding change is not backward compatible with pre-9.15 indices, which means that a full resync is required after the NDU (non-disruptive upgrade) commit.

The important details:

  • The resync is triggered automatically by the system after the upgrade commit when incompatible versions are detected. Administrators do not need to initiate it manually.
  • During the resync, do not interact with or interrupt the MetadataIQ service. Manual intervention during this process may cause the resync to fail, potentially requiring a manual reset and restart.
  • The resync duration depends on the size of the indexed dataset. Plan accordingly when scheduling the upgrade window.

In the event of an upgrade rollback, the producer and consumer services return to their pre-upgrade behavior automatically, resuming operation on the older version with the original schema.

Understanding how MetadataIQ’s services behave during each stage of a non-disruptive upgrade is helpful for planning:

It’s also worth understanding how the producer and consumer components behave through the upgrade lifecycle:

Phase Details
Pre-upgrade Both producer and consumer run on the older version. The producer continues generating changelists as normal, and the consumer transfers data using the existing pre-upgrade schema.
Post-upgrade (mixed version): The producer is disabled for the duration of the mixed-version window. The consumer adapts per node version — old schema on not-yet-upgraded nodes, updated logic on upgraded nodes — and transfers may pause or continue based on compatibility checks.
Post-commit After the automatic resync completes, the producer is re-enabled and resumes generating changelists, while the consumer updates the database mapping and begins transferring under the new schema.
Post-rollback If the upgrade is rolled back, both components simply return to their pre-upgrade behavior on the older version and the original schema.

To illustrate the behavior, consider two scenarios that demonstrate how the rename phase handles common directory operations.

Scenario 1: Simple nested renames

Starting from a nested directory structure:

# mkdir -p /ifs/data/A/B/C/D/E/F/G/H

After the initial MetadataIQ cycle, all eight directories are indexed in Elasticsearch with their full paths. Now, two renames are performed:

# mv /ifs/data/A/B /ifs/data/A/Bx

# mv /ifs/data/A/Bx/C/D/E /ifs/data/A/Bx/C/D/Ex

In prior releases, the descendants of those directories would have retained their old paths in the index. Instead, in OneFS 9.15, when the next MetadataIQ cycle runs, the transfer agent detects both rename events during primary processing and records the new paths in the rename_path field. Then, in the rename phase, it processes the renames in depth-descending order:

  • First, E → Ex is processed: /ifs/data/A/Bx/C/D/Ex/F, /ifs/data/A/Bx/C/D/Ex/F/G, and /ifs/data/A/Bx/C/D/Ex/F/G/H are all updated.
  • Then, B → Bx is processed: all remaining descendants under the old /ifs/data/A/B prefix are updated to /ifs/data/A/Bx.

The outcome is that all child paths are correctly updated in the database, and no stale entries remain.

Scenario 2: Subtree moves within the same tree

Starting from the same structure, this time with more complex operations:

# mkdir -p /ifs/data/A/B/C/D/E/F/G/H

# mv /ifs/data/A/B/C/D/E /ifs/data/A/

# mv /ifs/data/A/E/F/G /ifs/data/A/B/C/D/

# mv /ifs/data/A/B /ifs/data/A/Bx

Here, subtree E is moved up to become a direct child of A, subtree G is moved into D, and B is renamed to Bx. After the MetadataIQ cycle, the database reflects all three operations correctly:

  • E and its child F are now under /ifs/data/A/E and /ifs/data/A/E/F.
  • G and its child H are now under /ifs/data/A/Bx/C/D/G and /ifs/data/A/Bx/C/D/G/H.
  • B’s rename to Bx is propagated to all remaining descendants: /ifs/data/A/Bx/C, /ifs/data/A/Bx/C/D.

So, this results in no stale entries, nor a need for manual resync. The depth-descending processing order and the snapshot generation number atomicity ensure that even compound operations within the same tree are resolved correctly.

After a MetadataIQ cycle involving directory renames has completed, the following CLI utilities can be used to monitor and verify operation. This includes:

Checking the MetadataIQ services:

# isi services -a | grep -i metadataiq

Monitoring the ChangelistCreate job:

# isi job jobs list | grep -i ChangelistCreate

Confirming the MetadataIQ snapshot count (which should be <= 2 under healthy operating conditions):

# isi snapshot snapshots list | grep -i metadataiq

Additionally, to verify that rename propagation has completed successfully, the Elasticsearch index can be queried for any documents with a non-empty ‘rename_path’ field. In normal operation, the following query should return zero results after the transfer agent completes:

GET isi_metadata_index/_search

{

  "query": {

    "exists": {

      "field": "rename_path"

    }

  }

}

A non-zero result count indicates that rename processing was interrupted and will be completed on the next transfer agent invocation.

OneFS SmartSync Failover and Failback

Data replication is only half the equation. The other part, which often gets tested at the worst possible moment, is what happens when the primary cluster goes dark and storage administrators need to redirect clients to the secondary site with minimum disruption and maximum confidence in data integrity.

OneFS 9.15 introduces SmartSync failover and failback capabilities to ensure uninterrupted operations and fast recovery when a primary PowerScale cluster becomes unavailable. Rather than relying on time‑consuming restores from traditional backups, SmartSync enables rapid redirection of client access to a secondary cluster. By keeping data and metadata immediately available, it significantly reduces Recovery Time Objectives (RTO).

When the primary cluster is restored, SmartSync efficiently performs failback by syncing only the incremental changes generated during the failover period, preserving data integrity and enabling a seamless return to normal replication operations.

Together, these capabilities deliver a robust, high‑availability data mobility solution that strengthens business continuity and lowers operational risk.

SmartSync Failover/Failback provides the following capabilities:

·         Converts a read‑only SmartSync target path into a writeable path.

·         Switches a writeable SmartSync source path to read‑only.

·         Restores a SmartSync base path to a previous dataset state.

·         Enables reverse incremental synchronization to transfer client‑written data from a failover cluster back to the original source.

With OneFS SyncIQ, the allow-writes > resync-prep > redirect > reverse flow is generally well understood. In contrast, OneFS SmartSync has some notable variations to this theme, and it’s worth understanding how the SmartSync process differs before it’s actually required. This article walks through the full SmartSync failover and failback lifecycle, including what the commands do, why the sequence matters, and where the behavior diverges from what seasoned SyncIQ administrators will expect.

SmartSync replication is built on the Datamover service (isi_dm_d) and operates exclusively on Global Snapshots, referred to in its vernacular as ‘datasets’.

A dataset is an immutable, point-in-time view of the file system created via SnapshotIQ. Unlike a SyncIQ-replicated path, where the target is a live, writable mirror held read-only by convention, a SmartSync target path is backed by a series of versioned, lineage-aware datasets. This lineage is what makes efficient failback possible without re-baselining.

First, there are a few caveats to consider before getting into the workflow:

  • Failover and failback are supported only by file-to-file replication (PowerScale cluster to PowerScale cluster). File-to-object cloud copy does not support either operation.
  • The prerequisite state is a working repeat-copy relationship: a dataset creation policy running on the source and a repeat-copy policy replicating incrementally to the target. The baseline run must have completed successfully.
  • Both clusters must have mutual TLS trust established and replication accounts configured in both directions. Trust is symmetric by design, which is what makes role reversal possible without reconfiguring certificates.
  • The required privilege is ISI_PRIV_DATAMOVER. SmartSync also requires active SyncIQ and SnapshotIQ licenses on both clusters.

Workflow-wise, SmartSync failover and failback entails a seven-step process:

Steps 1 and 2 constitute the failover. Steps 3 through 5 constitute the failback. Steps 6 and 7 restore the original replication direction.

Step Action Details
1 Failover (part i) Make the target writeable; optionally revert to a clean dataset.
2 Failover (part ii) Client writes occur on the target; create a dataset to capture changes.
3 Failback (part i) Prepare the original source by reverting to the matching dataset.
4 Failback (part ii) Perform the reverse incremental sync from target back to source.
5 Failback (part iii) Make the original source writeable and redirect clients.
6 Reset (part i) Prepare the original target for forward replication (revert and make read-only).
7 Reset (part ii) Resume the original-direction repeat-copy policy.

In practice, a planned failover may compress some steps. Similarly, an unplanned failover may skip others depending on the state of the source cluster.

Step 1: Making the Target Writeable (and Optionally Reverting)

Under normal repeat-copy operation, the target base path is read-only. SmartSync enforces this to prevent data written on the target from conflicting with incoming incremental updates from the source. The failover action unlocks the path with a single command:

target-1# isi dm setup-dir client-access --base-path /ifs/tgt

Are you sure you would like to make base path /ifs/tgt writable? (yes/[no]): yes

Created job: 1.

Path will become writable.

In an unplanned failover where the source is simply unavailable, take the last replicated dataset and make it available for writes. However, in a ransomware or data-corruption scenario, the latest dataset on the target may itself be compromised. SmartSync addresses this with the ‘–dataset-revert’ option, which simultaneously makes the path writeable and rolls it back to a specific earlier dataset:

target-1# isi dm setup-dir client-access --base-path /ifs/tgt --dataset-revert 1

Are you sure you would like to revert base path /ifs/tgt to dataset ID 1? (yes/[no]): yes

Created job: 1.

Dataset will revert and path will become writable.

The dataset ID to revert to is identified beforehand using the ‘isi dm datasets list’ command, inspecting creation timestamps to find the last known-clean point in time. Once the revert completes, the target dataset that was reverted away from is removed from the dataset list, and the base path reflects the contents of the chosen dataset, ready for clients.

Step 2: Capturing Changes on the Failover Cluster

With clients now writing to the former target, a dataset creation policy is needed to capture those changes as Global Snapshots. This is necessary for Step 4 (failback sync) to have a reference point to sync from, and is created with a one-shot ‘run-now’ execution to immediately capture the current state, then configure recurrence for ongoing snapshots:

target-1# isi dm policies create fo_creation CREATION \

    --priority NORMAL \

    --run-now true \

    --creation-account-id local \

    --creation-base-path /ifs/tgt

Created policy: 1.

At this point, if the original source is to be permanently decommissioned, the workflow stops here. The former target is now a fully independent source cluster. A new repeat-copy policy can be defined pointing at a fresh target, and normal forward replication resumes from this cluster with no re-baselining required anywhere downstream.

Step 3: Preparing the Original Source for Failback

Failback mandates that the original source be in a state the reverse-direction incremental sync can build upon. Specifically, the source must contain no datasets under the base path that post-date the dataset the target was using when it became writeable. If the source was still receiving new datasets from a running dataset creation policy at the moment of failover, those newer datasets must be removed before failback can proceed.

The ‘isi dm setup-dir replication-target’ CLI command handles this. It always requires a dataset revert and makes the base path read-only, transforming the cluster from an active source into a replication target ready to receive data:

source-1# isi dm setup-dir replication-target --base-path /ifs/src --dataset-revert 2

Are you sure you would like to revert base path /ifs/src to dataset 2? (yes/[no]): yes

Created job: 1.

Dataset will revert and path will become read-only

Dataset IDs are cluster-local, not globally synchronized, so the dataset ID on the source cluster will generally differ from the corresponding ID on the target. The preferred approach is to match by dataset revision and tree ID, not by the local integer ID. Running ‘isi dm dataset view <id>’ on both clusters and comparing the Dataset Revision and Dataset Global ID fields allows the match to be confirmed before the revert is issued.

Note that, if the final dataset creation policy on the source is configured with the ‘–creation-dataset-make-read-only true’ argument, the source base path is automatically made read-only as soon as that dataset is created. Combined with a scheduled dataset creation immediately before the planned maintenance window, this eliminates the need to manually run replication-target on the source, and ensures no writes land between the last sync and the failover.

Step 4: Reverse Incremental Sync

This is where SmartSync’s re-baselining elimination pays off in the failback scenario. A reverse-direction repeat-copy policy is created from the failover cluster (now acting as source) back to the original source (now acting as target). The ‘–reconnect true’ flag instructs SmartSync to resume from the last shared dataset rather than initiating a full baseline copy. Without it, the first run would transfer the entire dataset unnecessarily.

target-1# isi dm policies create failback_rc REPEAT_COPY \

    --priority NORMAL \

    --run-now true \

    --repeat-copy-source-base-path /ifs/tgt \

    --repeat-copy-base-source-account-id local \

    --repeat-copy-base-target-account-id <source-cluster-account-id> \

    --repeat-copy-base-target-base-path /ifs/src \

    --reconnect true \

    --repeat-copy-base-target-dataset-type FILE

Created policy: 1025.

After the run completes, the job type can be verified in the ‘isi dm reports list’ command output. The type should be marked as ‘DATASET_INCREMENTAL’, confirming that SmartSync found the shared lineage and performed an incremental transfer rather than a full baseline. If it shows ‘DATASET_BASELINE’, the dataset revision match between the two clusters was incorrect and the revert (step 3) needs revisiting.

Step 5: Redirecting Clients Back to the Original Source

Once the failback sync has completed and the original source base path is current, the clients can be redirected. The ‘isi dm setup-dir client-access’ CLI command makes the path writeable without requiring a dataset revert, which is appropriate when the source is known-clean and the reverse sync is current:

source-1# isi dm setup-dir client-access --base-path /ifs/src

Are you sure you would like to make base path /ifs/src writable? (yes/[no]): yes

Created job: 1.

Path will become writable.

Following this, any pertinent DNS entries, SmartConnect zone configuration, or NFS mount points can be updated as appropriate to redirect client traffic. The original source is now serving live client workloads again.

Step 6: Prepare the Original Target for Forward Sync

With clients back on the original source, the final pair of steps (steps 6 & 7) restores the normal A-to-B replication direction. First, the former failover cluster (B) is prep’d to become a replication target again. As such, any datasets created on it since the last successful reverse sync are reverted away, and the path is made read-only.

target-1# isi dm setup-dir replication-target \

    --base-path /ifs/tgt \

    --dataset-revert <latest-shared-dataset-id>
Step 7: Resume the Original Replication Direction

With the original target read-only and aligned to the same dataset revision as the source, the original forward repeat-copy policy is resumed with a manual ‘run-now’ trigger. SmartSync uses the shared lineage to perform an incremental update, again with no re-baseline:

source-1# isi dm policies modify <original-policy-id> --run-now true

Once this job completes successfully, the relationship is back to its pre-failover state: Source writeable, target read-only, incremental replication running on schedule. As such, the full cycle is complete.

PowerScale cluster admins who are familiar with SyncIQ will notice both familiar patterns plus notable differences when it comes to managing SmartSync failover. The following table summarizes the key operational distinctions:

Aspect SyncIQ SmartSync
Failover command isi sync policies modify –action allow-writes isi dm setup-dir client-access
Source lock for failback Implicit: resync-prep job prepares source as target Explicit: isi dm setup-dir replication-target (always requires revert)
Re-baselining on failback Not required (changelist-based incremental) Not required (Global Snapshot lineage, –reconnect true)
Ransomware / data corruption recovery Fail over to last clean sync snapshot via isi snapshot restore Integrated: –dataset-revert in same failover command
Reverse sync direction New SyncIQ policy, source becomes target New REPEAT_COPY policy with –reconnect true from failover cluster
Restoring forward direction Disable reverse policy; re-enable original policy setup-dir replication-target on ex-target; modify original policy –run-now
Object / cloud replication Not applicable (file only) Cloud copy does not support failover or failback


SmartSync provides two views into replication state during and after a failover or failback operation. Running jobs appear in ‘isi dm jobs list’; completed jobs move to ‘isi dm reports list’. For granular job detail, the ‘isi dm job view <id>’ CLI command provides per-task progress, and ‘isi_datamover_job_status <id>’ gives lower-level internal state. Transfer failures write a job-specific log to ‘/ifs/data/Isilon_Support/datamover/transfer_failures/<job-id>/’, and the primary log file is ‘/var/log/isi_dm.log’.

For RPO visibility across replication relationships, particularly useful in the lead-up to a planned failover, the ‘isi dm rpo reports list’ CLI command provides a per-policy view of how current the replicated data is relative to defined recovery objectives.

SmartSync’s support for pull policies, where the target cluster initiates and pulls data from the source, adds a useful dimension to DR topology design that SyncIQ does not offer. In a resource-constrained source cluster, configuring the target to pull rather than the source to push offloads the replication compute burden to the DR site, leaving primary client I/O unaffected.

For the failback reverse sync specifically (Step 4), the policy is always issued from the cluster that holds the current writeable data, pushing to the recovering original source. There is no functional difference in the failover/failback sequence between clusters that used push versus pull in normal operations; both directions use the same commands. The key is that account IDs and base paths are swapped to reflect the reversed roles.

SmartSync failover and failback is a structured, seven-step workflow anchored on Global Snapshot lineage and three core commands: ‘isi dm setup-dir client-access’ (unlock a path for writes), ‘isi dm setup-dir replication-target’ (lock a path as a replication target and revert to a known state), and a reverse ‘REPEAT_COPY’ policy with ‘–reconnect true’ (incremental failback without re-baselining). The sequence handles both unplanned outage (fail over to last clean dataset, write locally, sync back) and planned maintenance (using the ‘–creation-dataset-make-read-only’ flag to cleanly quiesce the source before cutover).

Note the following important differences from SyncIQ: There is no equivalent of the ‘resync-prep job’, The ‘isi dm setup-dir replication-target’ CLI command, and its mandatory dataset revert, serve that function. Dataset ID matching between clusters is by revision and global ID, not by local integer. And –reconnect true on the reverse repeat-copy policy is non-negotiable for incremental failback.

Note also that SmartSync failover and failback is only supported for file-to-file replication. File-to-object cloud copy (replication to ECS, AWS, Azure, or GCP) does not support these operations and is intended for backup and archival workflows only. Verify the Job Type field in ‘isi dm reports list’ after a reconnect-mode failback sync: It must read ‘DATASET_INCREMENTAL’ to confirm that no re-baseline occurred.

PowerScale Software-Defined Exascale Platform

Building on the success of the PowerScale F910 and F710 all-flash platforms and the recently launched OneFS 9.15 release comes the debut of a fundamentally new addition to the PowerScale family: the software-defined Exascale node, based on the Dell PowerEdge R7725xd platform.

This marks a significant architectural milestone for PowerScale, introducing both the first AMD-based node in the product’s history and a notable enhancement to the traditional appliance delivery model that has defined the platform since its Isilon origins.

Predicated upon the 17th generation Dell PowerEdge R7725xd, the new Exascale node pairs dual-socket AMD EPYC SP5 processors with PCIe Gen5 all-flash NVMe storage, high-bandwidth 400GbE networking, and a generous helping of DDR5 memory — all in a standard 2RU chassis.

What makes it truly distinctive, however, is not just the hardware profile but the way it is delivered: Hardware and OneFS software are procured and shipped separately, and the node is not pre-configured as a dedicated storage appliance at the factory.

Customers purchase Exascale through standard Dell server sales channels and receive OneFS as a separate software license — meaning the same physical hardware can support PowerScale, ObjectScale, and in the future, PowerFlex, and Lightning File System workloads, depending on how the organization’s needs evolve.

A New CPU Architecture for PowerScale

Introducing AMD to the PowerScale lineup is not a minor footnote. AMD’s EPYC architecture has become the CPU of choice across the hyperscaler and AI/ML communities, and its presence in the PowerScale portfolio provides opportunities where Intel-only offerings have historically been a limitation. Each Exascale node is equipped with two AMD EPYC SP5 9455 processors — 48 cores each, running at a base clock of 3.15 GHz with a boost to 4.4 GHz, with 300W TDP (thermal design power) and 256 MB of L3 cache per socket. That is 96 cores per node, a significant step up from the 48-core (dual 24-core Sapphire Rapids) configuration of the F910, and it brings commensurate improvements in throughput-heavy and parallel workloads such as generative AI data pipelines, EDA, and high-concurrency analytics.

Accompanying the new CPUs is a whopping 768 GB of DDR5-6400 memory per node — 24 DIMMs at 32 GB each — compared to the 512 GB DDR5 configuration of the F910. This additional memory headroom benefits caching, metadata handling, and concurrent client workload density.

Storage and Journal

Each Exascale node accommodates 24 NVMe U.2 SSDs connected via PCIe Gen5 x4 lanes per drive. Five drive capacity points are supported, spanning from 7.68 TB TLC up to 122 TB QLC, yielding raw per-node capacities from 184 TB at the entry point all the way to 2.88 PB with the highest-density QLC option. That last figure is what earns the platform its Exascale designation — at maximum density, a fully populated cluster of Exascale nodes can reach raw capacities that were previously the exclusive domain of purpose-built hyperscale infrastructure.

The journal subsystem receives an equally significant upgrade. The Exascale platform ships with a 64 GB Software Defined Persistent Memory (SDPM) module — double the 32 GB SDPM introduced with the PowerScale F-series family. This is also the first SDPM implementation on an AMD platform, requiring a new SDPM design that integrates with the AMD memory controller architecture. SDPM continues to serve its established role as the persistent storage backing for the OneFS journal, providing the durability guarantees that protect in-flight write operations without the limitations of earlier NVDIMM-n technology.

On the system boot media side, the legacy IDSDM microSD configuration is replaced by a BOSS (Boot Optimized Storage Solution) N-1 DC-MHS module — a pair of dual-mirrored 960 GB ISE SSDs — providing a more robust and higher-capacity platform for node operating system and configuration storage.

400GbE Front- and Back-End Networking

Both front-end client and back-end intra-cluster networking on the Exascale platform step up to 400 GbE, a fourfold increase over the 100 GbE back-end configuration of the F910. Each interface is delivered via an NVIDIA ConnectX-8 dual-port 400 GbE adapter running over PCIe Gen5.0 x16, paired with NVIDIA Spectrum-SN5610 switches. Unlike the F910, InfiniBand is not supported — Exascale is an Ethernet-only platform — and the management port moves from a LOM (LAN-on-Motherboard) to a dual-port OCP 3.0 NIC operating at 1 GbE.

Licensing

Consistent with the software-defined delivery model, Exascale employs a dynamic licensing approach for PowerScale: a subscription-based license with an expiration date, rather than the traditional perpetual hardware-bundled license. A new single eLicensing tier covers the Exascale nodes, which can coexist alongside traditional PowerScale F-series, H-series, and A-series nodes within the same cluster under unified licensing management.

Specs

The basic specifications for the new Exascale hardware platform are:

Component Exascale Platform
Platform Dell PowerEdge R7725xd
CPU Dual-socket AMD EPYC SP5 9455, 48c, 3.15 GHz / 4.4 GHz
Memory 768 GB DDR5-6400 (24 × 32 GB)
Journal 64 GB SDPM
NVMe drives per node 24 × NVMe U.2 (PCIe Gen5 x4)
Drive options 7.68 TB, 15.36 TB (TLC) ; 30.72 TB, 61 TB, 122 TB (QLC)
Raw capacity per node 184 TB to 2.88 PB
Front-end network 2 × 400 GbE
Back-end network 2 × 400 GbE
Management 2 × 1 GbE OCP 3.0
Data reduction Software compression and deduplication
Form factor 2RU
Minimum OneFS 9.15

Deployment and Compatibility

In its PowerScale guise, the Exascale platform requires OneFS 9.15 as the minimum software version, along with Node Firmware Package (NFP) 14.1 minimum. Deployment is supported via a manual process performed by Dell Professional Services, or through the new Exascale Phase 1 Pave — a more automated, multi-node provisioning process capable of deploying either PowerScale or ObjectScale on the same hardware. Software and firmware upgrade procedures remain consistent with prior PowerScale generations.

In a future article, we’ll take a deeper look at the Exascale platform internals and interconnects, including the storage options, SDPM implementation, PCIe topology, and network connectivity in more detail. But in summary, the PowerScale Exascale platform quite simply redefines what a PowerScale node can be: Exascale-class capacity, next-generation AMD performance, 400 GbE throughout, and the operational flexibility of a truly software-defined delivery model — all in a compact and powerful 2RU form factor.

PowerScale InsightIQ 6.4

The dog days of summer have done nothing to slow the pace over at Dell PowerScale. Hot on the heels of the OneFS 9.15 release comes the arrival of the latest and greatest PowerScale InsightIQ 6.4 monitoring and reporting release.

As a quick refresher, InsightIQ provides robust health, performance, and reporting capabilities that help maximize PowerScale cluster efficiency, including advanced analytics to optimize applications, correlate cluster events, and accurately forecast future storage requirements.

So what goodness does this InsightIQ 6.4 release add to the PowerScale metrics and monitoring mix?

New functionality includes:

Feature IIQ 6.4 Functionality
Top Talkers Report New report type surfacing the top N clients slowing a cluster down, ranked by bandwidth, latency, and operation rate.
Performance Anomaly Detection On-demand anomaly detection across the Performance Reports modules, highlighting unusual behavior directly on the existing performance graphs.
Dell ESE Integration Secure, always-on connectivity to Dell support infrastructure via Connectivity Services, enabling remote troubleshooting without VPN or direct network access.
Telemetry Automated, periodic collection of system health, configuration, and feature-adoption metadata, uploaded securely over the same ESE channel. No customer PII or cluster data.
Partitioned Performance Enhancements New SmartQoS identification and workload-latency metrics, plus support for 1,024+ workloads per dataset.
AI Assistant Enhancements Bring Your Own LLM (BYO-LLM) support, multi-session chat history, and response-feedback collection.
Platform & OS Support Support for the latest OS and OneFS releases, plus N-2 version upgrade support for simplified upgrade planning.

The new PowerScale InsightIQ 6.4 release introduces a healthy crop of enhancements aimed at improving performance visibility, supportability, and day-to-day usability. Let’s take a closer look at each of them in turn.

Top Talkers Report

Top of the bill in 6.4 is the new Top Talkers report, added to the Performance Reports family. Rather than trawling through graphs to work out which client is hammering a cluster, administrators can now see the busiest clients at a glance. The report presents bar charts of the top N clients across three brand-new modules — Bandwidth, Latency, and Op Rate — making it straightforward to pinpoint the workloads that are slowing a monitored cluster down.

Because Top Talkers lives within Performance Reports, it behaves just like its siblings: the usual filters can be applied (single-value filters are supported for these new modules), and the modules can be freely mixed and matched into custom user-defined reports.

Performance Anomaly Detection

InsightIQ 6.4 also gains on-demand Performance Anomaly Detection — a built-in capability that automatically flags unusual performance patterns on your monitored clusters. Anomalies are highlighted directly on the existing performance reporting graphs, with InsightIQ computing expected upper and lower confidence bounds for each metric and marking any data point that breaches them. It works across all performance report types, with the sole exception of multiline graphs.

Two detection modes are on offer, depending on how much history is available:

Historic Mode Current View Mode
Uses past trends and seasonality (hourly, daily, weekly) to establish a baseline. Detects anomalies using only the data visible on the current graph.
Requires a minimum of one week of historical data. Works for any selected time duration.
Configurable lookback window of 1, 2, or 3 weeks (default: 2 weeks). No historical data requirement.
Best for steady-state workloads with predictable patterns. Useful when historical data is limited or the cluster is newly added.

Three sensitivity levels — Low, Medium, and High — control the strictness of the confidence bounds, with higher sensitivity flagging subtler deviations. Historic mode builds its baseline from up to three weeks of past data, learning the hourly, daily, and weekly seasonality unique to each cluster’s workload. To use Historic mode, at least one PowerScale cluster must be added, actively monitored, in a Connected state, and have a minimum of one week of collected performance data.

Dell ESE Integration (Connectivity Services)

Arguably the headline supportability feature of the release, InsightIQ 6.4 introduces integration with Dell’s backend through ESE Connectivity Services. This establishes secure, always-on connectivity between InsightIQ and Dell Technologies support infrastructure, allowing Dell support engineers to remotely access and troubleshoot an InsightIQ instance without requiring a VPN, direct network access, or customer-side coordination during the session. Once configured, a dedicated support user is automatically provisioned for those remote sessions.

Two core capabilities ride on this new channel:

  • Remote Support — Dell support engineers can initiate secure remote CLI (SSH) or Web UI sessions to the InsightIQ instance, authenticated via a time-limited RSC passcode tied to an active Service Request.
  • Auto Support Case Creation — InsightIQ can automatically open support cases with Dell when qualifying events are detected. This can be enabled in the 6.4 release, though it is not yet internally active.

Connectivity can be established in one of two modes, depending on whether the InsightIQ instance is permitted direct internet access:

Connection Mode Description
Connect Directly InsightIQ connects out over the internet directly to Dell Connectivity Services. Requires outbound internet access from the IIQ instance.
Via Secure Connect Gateway InsightIQ connects over port 9443 to a Secure Connect Gateway (SCG) appliance, which acts as a secure proxy to Dell Connectivity Services — useful when IIQ cannot have direct internet access. IIQ monitors only its connection to the gateway; the gateway-to-Dell link is not checked by IIQ. The SCG appliance must be acquired and set up independently.

From a security standpoint, the auto-provisioned support user is deliberately constrained. Via the Web UI it holds a read-only role — able to view the InsightIQ interface but unable to modify any settings or data. Via CLI (SSH) it is limited to non-disruptive operations such as log collection and diagnostics; session-disrupting operations are blocked, with the sole exception of ‘system-reboot’. All remote sessions auto-terminate after 20 minutes of inactivity, and the support user’s credentials are managed internally by InsightIQ and the Dell backend, rather than by IIQ users. Prerequisites are modest: a machine-id (/etc/machine-id) must be present on Scale setups, and an Access Key and PIN are generated up front via the Dell support portal.

Telemetry

Complementing the ESE integration, InsightIQ 6.4 adds Telemetry — the automated, periodic collection of operational metrics and configuration data from InsightIQ, securely uploaded to the Dell ESE connectivity hub. Telemetry rides on the very same connectivity channel and runs quietly in the background as long as connectivity is enabled; no customer action is required after the initial setup. Data is gathered at staggered intervals, compressed into timestamped .tar.gz archives, and uploaded with MD5 checksum integrity verification. Crucially, no customer PII or cluster data content is collected — only system health, configuration metadata, and operational counters.

The collected data gives Dell health monitoring (IIQ health status, cluster connectivity, and critical alerts), deployment visibility (version, deployment mode, host specs, and cluster configuration across the installed base), and feature-adoption insight (which features such as FSA, Quotas, Dedupe, Performance Reporting, and the AI Assistant are actively in use). The collection cadence is pre-configured as follows:

Frequency Data Collected
Every 15 minutes Overall IIQ health; clusters with data-collection failures; critical alerts in the last 15 minutes.
Every 1 hour Cluster connectivity status; datastore usage %; node count; OneFS version; per-cluster node health (nodes up vs. nodes down).
Every 4 hours Total node count across all monitored clusters; per-cluster feature availability (FSA, Quotas, Dedupe).
Every 24 hours Alerts generated in the last 24h; storage usage (percent used, total capacity, per-cluster DB size); deployment info (version, Simple/Scale mode); host info (OS & kernel, CPU cores, RAM, IIQ storage used); alert configuration; performance-reporting configuration; and AI Assistant feedback.

Partitioned Performance Report Enhancements

Keeping step with the latest PowerScale release, InsightIQ 6.4 extends its Partitioned Performance reporting to embrace the newest SmartQoS capabilities. Three enhancements land here:

  • New identification metrics — The new Identification Metrics for performance datasets — Operation Class and File — are now displayed in the breakout values and can be filtered on as normal.
  • Workload latency metrics — The new latency metrics ReadQoSDelay, WriteQoSDelay, and OtherQoSDelay appear as three new lines in the Workload Latency graph, with breakouts displayed as normal when selected from the Breakout By dropdown — a boon for SmartQoS latency analysis.
  • More workloads per dataset — Support has been added for OneFS’s new configurable workload limit, so InsightIQ now handles 1,024+ workloads per user-defined dataset. Dell recommends bumping the deployment VM to 12 CPUs and 32 GB RAM to comfortably absorb the higher expected load.

AI Assistant Enhancements

The document-aware AI Assistant introduced in InsightIQ 6.3 — the intelligent companion that helps users find information, understand product capabilities, and troubleshoot InsightIQ and PowerScale issues directly within the interface — receives a trio of enhancements in 6.4:

  • Bring Your Own LLM (BYO-LLM) — Enables integration with an external, OpenAI-compatible LLM. User queries can be securely routed to the configured external model for response generation, rather than relying solely on the built-in assistant.
  • Chat history — Supports multiple chat sessions, letting users switch between conversations while maintaining context across interactions.
  • Response feedback — Lets users rate the AI-generated responses. That feedback is gathered through telemetry to help improve the overall experience over time.

Enabling the AI Assistant is a prerequisite for all of the above. For BYO-LLM specifically, an OpenAI-compatible API endpoint, valid API credentials, and — where applicable — the required SSL/TLS certificates are needed.

Ecosystem & Platform Support

On the platform front, InsightIQ 6.4 keeps pace with the latest operating system and OneFS releases. The headline changes since 6.3 are the move to SLES 15 SP6 for Scale deployments and extended PowerScale coverage up to OneFS 9.15. The full qualification matrix is as follows:

Qualified On InsightIQ 6.3 InsightIQ 6.4
OS (Scale deployment) RHEL 8.10, RHEL 9.6, RHEL 10.0, SLES 15 SP4 RHEL 8.10, RHEL 9.6, RHEL 10.0, SLES 15 SP6
PowerScale (OneFS) v9.7 to v9.14 v9.7 to v9.15
VMware ESXi ESXi v8.0 U3, ESXi v9.0.1 ESXi v8.0 U3, ESXi v9.0.1
VMware Workstation Workstation 17 Free Version Workstation 17 Free Version
Ubuntu Ubuntu 24.04 Online deployment Ubuntu 24.04 Online deployment
OpenStack RHOSP v21 with RHEL 10.0 RHOSP v21 with RHEL 10.0

As with prior releases, InsightIQ continues to offer the same two deployment models — the bare-metal / virtual-machine InsightIQ Scale flavour and the OVA-based InsightIQ Simple flavour on a VMware hypervisor — so existing customers can stick with the model that best suits their environment.

Upgrading to InsightIQ 6.4

One of the more welcome operational touches in this release is N-2 upgrade support, which simplifies upgrade planning by allowing a direct, in-place upgrade to 6.4 from either the 6.2.0 or 6.3.0 release — the process is identical on both Simple and Scale deployments. Beyond an existing InsightIQ Simple or Scale machine running 6.2.0 or 6.3.0, the only real prerequisite is at least 40 GB of free disk space.

At a high level, the upgrade is driven by a single script and moves through a precheck, the upgrade itself, and a post-upgrade cleanup:

  • Precheck — Docker availability, an InsightIQ version check (6.2.0 or 6.3.0), free disk space, InsightIQ service status, and OS compatibility.
  • Upgrade — EULA acceptance, extraction of the InsightIQ images, service shutdown, resource-limit updates, add-on and CIAM installation, and the InsightIQ service upgrade itself.
  • Post-upgrade — InsightIQ metadata refresh, re-enabling of the AI Assistant (if opted in), removal of old Docker images, and clean-up of the upgrade and backup folders.

The mechanics themselves are refreshingly simple — download and uncompress the bundle, extract the upgrade scripts, and trigger ./upgrade-iiq.sh. Progress can be tracked at any time with the showupg –log and showupg –status helpers, with the full detail available in the insightiq_upgrade.log under /usr/share/storagemonitoring/logs/.

All told, InsightIQ 6.4 is a hearty release: Top Talkers and Performance Anomaly Detection sharpen the day-to-day performance story, the ESE integration and Telemetry step change the supportability experience, and the SmartQoS, AI Assistant, and platform updates round things out nicely.

ObjectScale 4.4 and X7700 Platform

Hot off the press comes ObjectScale version 4.4 – a significant release of Dell’s enterprise-grade object storage platform and a key component of the Dell AI Data Platform. ObjectScale 4.4 builds on the foundation laid by earlier releases, delivering broad improvements across performance, security, observability, networking, and licensing that are engineered to meet the evolving demands of AI-driven and cloud-native workloads. Version 4.4 also arrives alongside the new Dell ObjectScale X7700, the ultra-dense HDD storage engine of the Dell AI Data Platform, whose launch highlights are summarized later in this article.

This release is available as a software upgrade for existing ObjectScale environments. The core new customer-facing features and capabilities introduced in ObjectScale 4.4 include:

Performance and Storage Efficiency

ObjectScale 4.4 compacts data indices to improve garbage collection (GC) throughput, enabling faster reclamation of deleted capacity and reducing the operational overhead associated with large-scale object churn. This release also extends support for large object storage workloads, broadening the platform’s applicability for AI training datasets, media archives, and other use cases characterized by very large individual objects.

Targeted performance tuning for Big AI workloads includes shared memory (SHM) refactoring to reduce contention and improve throughput under heavy parallel data access patterns typical of model training and inference pipelines. These optimizations are designed to complement ObjectScale’s role in the Dell AI Data Platform, ensuring that storage I/O does not become a bottleneck for GPU-intensive workloads.

S3 object listing operations now benefit from prefetching, reducing latency when enumerating large buckets. This improvement is particularly impactful for AI data pipelines and analytics workflows that iterate over millions of objects as part of data ingestion or cataloging processes.

Metadata journal garbage collection is now enabled by default in ObjectScale 4.4, improving storage efficiency and reducing administrative overhead by ensuring that metadata journal data is reclaimed automatically without manual intervention. Retention policies have also been optimized to reduce configuration complexity and improve long-term cluster hygiene in geo-replicated environments.

Capacity metrics reporting has been enhanced for greater accuracy, particularly for chunked and geo-replicated data where previous releases could undercount or misrepresent consumed capacity in the dashboard. A related fix corrects inaccurate UI report data for geo-replication configurations, giving administrators a more reliable view of storage utilization across multi-site deployments.

Networking and Connectivity

ObjectScale 4.4 includes S3 over RDMA, using the RoCE v2 (RDMA over Converged Ethernet version 2) protocol, and delivering significantly lower latency and higher throughput for object I/O compared to standard TCP-based S3. This capability is targeted at performance-intensive workloads such as AI/ML training, high-performance analytics, and large-scale data ingest where network latency is a bottleneck.

Enabling S3 on RDMA requires a compatible lossless Ethernet fabric configured with Priority Flow Control (PFC), Explicit Congestion Notification (ECN), and appropriate QoS settings. Note that this feature is disabled by default and must be enabled by engineering on a case-by-case basis while NVIDIA driver certification is completed.

ObjectScale 4.4 introduces load balancer support for Sonic switches, enabling improved traffic distribution across network paths in software-defined and open-networking deployments. This enhancement provides greater flexibility in network architecture design and supports higher aggregate throughput for environments using Sonic-based switching fabrics.

The connectivity framework introduces two new automated behaviors in 4.4: a daily cluster topology transmission to the Dell connectivity portal in AST format, and an hourly heartbeat and connection test. These additions improve proactive monitoring visibility and support faster issue detection and resolution by Dell support teams. The product type on the connectivity portal for key and PIN generation remains “Elastic Cloud Storage Gateway.”

ObjectScale software-defined deployments now support single NIC configurations, including both single-port and dual-port single NIC topologies. This reduces the hardware footprint and simplifies cabling for software-defined environments. Note that this capability is Request for Price Quotation (RPQ)-only for the 4.4 release and must be scoped and approved by the product group prior to deployment.

Security and Platform Hardening

ObjectScale 4.4 introduces a new platform hardening capability that substantially reduces the OS-level attack surface by transitioning the deny list for Object Storage services (OBS) to an allow-list model. When enabled, the escalation tool requires a password configured by the administrator via the UI; the platform internally combines this password with the node service tag using PBKDF2 key derivation, which is entirely transparent to the end user.

Platform hardening is disabled by default in ObjectScale 4.4 for both fresh installs and upgrades, and must be explicitly enabled via the UI or API with an escalation password. It is important to note that this feature is distinct from STIG hardening, which is not included in the 4.4 release.

Root CA rotation for ECS service-level communications is now fully automated in ObjectScale 4.4, eliminating the need for manual tracking and intervention before certificate expiry. In prior releases, administrators were responsible for proactively monitoring and rotating the root CA before it expired. This automation removes a significant operational risk and reduces the burden on storage administrators managing large or distributed ObjectScale environments.

Two combined security capabilities address elevated container privilege mode exposure within the ObjectScale container runtime. These changes reduce the risk associated with privileged containers by enforcing stricter privilege boundaries, contributing to a more secure and defensible platform posture.

The UI’s backend-for-frontend (BFF) layer has been upgraded and rewritten to address security vulnerabilities in the prior implementation. This update modernizes the communication layer between the management UI and backend services, incorporating current security best practices and reducing the exploitable surface area of the management interface.

Observability and Operations

The ObjectScale management UI has received a comprehensive visual refresh in version 4.4, delivering a modernized design and improved user experience across dashboards, configuration workflows, and status views. The updated interface aligns with current Dell design standards and aims to reduce the time administrators spend navigating the management plane.

ObjectScale 4.4 empowers administrators to self-execute pre-upgrade health checks without engaging Dell Professional Services. Using a service orchestrator container (Stargate) available exclusively from 4.4 onwards, customers can trigger health checks via REST API calls before scheduling a maintenance window. The checks validate all current pre-upgrade conditions, including firmware versions and system readiness, helping to surface potential issues early and reduce maintenance window duration.

Documentation for this feature will be included in the ObjectScale Admin Guide. The capability is available only on clusters running ObjectScale 4.4 or later.

ObjectScale 4.4 introduces native Kafka-based event notification support, enabling external systems to consume ObjectScale events – such as object creation, deletion, or policy changes – via Kafka topics. This complements existing webhook-based notifications and is particularly valuable for organizations that have standardized on Kafka as their event streaming backbone for data pipelines and event-driven applications.

An S3 request throttler is introduced in ObjectScale 4.4 as an initial MVP capability, allowing administrators to apply rate limits to S3 operations to prevent any single tenant, application, or workload from exhausting cluster resources. This provides a foundational quality-of-service control mechanism that will be expanded in future releases.

ObjectScale 4.4 delivers S3 Tables at general availability, providing native Apache Iceberg support directly within the platform. Analytics and AI workloads can query and operate on tabular data in place, eliminating the need to move or copy data into a separate analytics engine. A complementary S3 Tables reporting capability surfaces structured visibility into S3 table utilization and access patterns within the ObjectScale management layer, with richer analytics to follow in subsequent releases.

The hashing algorithm underlying ObjectScale’s metering subsystem has been redesigned to improve accuracy and performance of usage data collection. This change ensures that consumption reporting is more precise and scales more efficiently as cluster size and object count grow, which is increasingly important in multi-tenant and pay-per-use licensing scenarios.

Licensing

Dynamic licensing in ObjectScale 4.4 adds Multi-License Aggregation Group (Multi-LAG) support, allowing administrators to manage and aggregate multiple license groups through a unified workflow. Accompanying UI enhancements provide clearer visibility into LAG composition and licensing status, reducing administrative complexity for large or multi-tenant deployments.

ObjectScale 4.4 extends dynamic licensing to better support Transformational License Agreement (TLA) customers. TLA customers – typically software-defined deployments – select a TLA checkbox during SCG configuration, which triggers a dedicated dynamic licensing registration workflow. Without this selection, the system would attempt standard registration, which requires hardware device service tags (DSTs) not present in software-defined environments.

The SCG configuration UI and documentation have been reviewed and updated to consistently use the correct term “Transformational License Agreement” throughout, resolving prior inconsistencies between screens.

For environments where ObjectScale cannot maintain continuous connectivity to the Dell licensing portal, offline compliance reporting provides a mechanism for periodic compliance validation and evidence generation. This is particularly relevant for air-gapped or intermittently connected deployments that must still satisfy licensing obligations.

Hardware Platform Additions

ObjectScale 4.4 qualifies two new drive configurations, expanding the storage density options available to customers:

  • 61 TB Self-Encrypting Drive (SED) on XF960: Qualifies the 61 TB SED for the XF960 all-flash appliance, delivering higher all-flash storage density while maintaining full data-at-rest encryption and security. No user behavior changes are required.
  • 122 TB and 245 TB Drive Support (software-defined): Qualifies high-density 122 TB and 245 TB drives for ObjectScale software-defined deployments, enabling greater storage efficiency with fewer servers and a lower datacenter footprint. No user behavior changes are required.

ObjectScale 4.4 also introduces software delivery support for the X7700 platform (single chassis, 102 drives). Dual chassis qualification is in progress and will be released in a subsequent update. For ObjectScale software-defined deployments on the 7725XD platform, single NIC support (RPQ) is now available as described above.

ObjectScale X7700 Platform

ObjectScale 4.4 launches alongside the new Dell ObjectScale X7700, the ultra-dense HDD object storage engine and dense bulk tier of the Dell AI Data Platform.

Built on a disaggregated 1U compute and 4U storage design, the X7700 pairs the 4.4 software capabilities described above with a significant step up in density, performance, and economics. Highlights include:

  • Up to 45% more HDD capacity in the same footprint, allowing environments to scale without consuming additional data center floor space.
  • Up to 3x faster object read and write performance compared to ECS EX5000 running 4.3, with a single-node X7700 delivering performance equivalent to a previous-generation dual-node EX5000 for most use cases.
  • 100GbE front-end networking, delivering up to 4x faster throughput than the prior generation and shrinking backup and restore windows.
  • Structured data queried in place with production-ready S3 Tables and Apache Iceberg, up to 4.5x faster with no data movement, complemented by up to 3x faster S3 listing versus 4.3.
  • Seamless ECS and ObjectScale intermix: X7700 nodes can be added to existing live clusters after the appropriate software upgrade, protecting prior infrastructure investment.
  • Up to 80% lower total cost of ownership compared with leading public clouds in active-storage scenarios, per Omdia economic validation sponsored by Dell Technologies.

In summary, ObjectScale 4.4 represents a substantial advancement across the dimensions of the platform – from AI workload performance and RDMA networking to automated security hardening, self-service operations, and flexible licensing. Whether deploying on the latest X7700 hardware, extending into software-defined configurations, or upgrading an existing ECS or ObjectScale environment, this release equips organizations with the tools needed to manage growing data volumes with greater efficiency, security, and confidence.

OneFS pNFS Configuration and Management

As we saw in the previous article in this series, with OneFS 9.15, any node in a PowerScale cluster can now act as the OneFS metadata server (MDS), or serve data connections (DS). This separation of the metadata path from the data path allows file I/O traffic to be distributed across multiple nodes in the cluster, thereby maximizing available bandwidth and parallelism.

In this article, we turn our attention to the enablement, configuration, and management of pNFS.

When a pNFS‑capable client mounts an NFS export on a pNFS‑enabled OneFS cluster, each node functions as both a Metadata Server and a Data Server, with the Metadata Server role being implicitly assigned to the node the client initially contacts during the mount.

Data I/O operations are performed using NFSv3, as permitted by the pNFS Flexible File Layout specification, while NFSv4.1 or NFSv4.2 is used exclusively for layout management and metadata operations. Layouts are granted on a per‑file basis, with the client requesting a layout upon file open that specifies the appropriate data server or servers for that file. Different files may be assigned to different nodes, and traffic distribution behavior is influenced by server‑side alignment settings. The set of data server addresses provided to the client is determined by the SmartConnect pool associated with the mount IP address.

In order for pNFS to activated, a cluster must be running OneFS 9.15, with NFSv4.1 or NFSv4.2 enabled for metadata operations and NFSv3 enabled for data operations. The SmartConnect pool must also use static IP allocation.

Attribute Details
OneFS version OneFS 9.15 to provide pNFS support.
NFS protocol versions NFSv4.1 or NFSv4.2 must be enabled (for the metadata path). NFSv3 must also be enabled (for the data path).
SmartConnect pool type The SmartConnect network pool hosting pNFS must use Static IP allocation.
Client OS Linux with kernel pNFS Flexible File Layout support (available in mainline Linux kernels 5.14+).
Client mount options The client must mount the cluster export using NFSv4.1 (-o vers=4.1) or NFSv4.2 (-o vers=4.2). Transport protocol may be RDMA (proto=rdma) or TCP (proto=tcp). UDP is unsupported.

On the client side, systems must be running Linux kernels that support the pNFS Flexible File Layout, which is available in mainline kernels version 5.14 and later. Additionally, mounts must explicitly specify NFSv4.1 or NFSv4.2 using either TCP or RDMA transport, as UDP is not supported.

With OneFS 9.15, pNFS configuration can be performed via the OneFS CLI or platform API (pAPI), but the WebUI does not currently have an equivalent. Under the hood, the configuration is managed by the  ‘isi_gconfig’ registry keys under the NFS driver path. Client remounts are strongly recommended when enabling or disabling pNFS, as clients cache file attributes that determine layout eligibility, so may otherwise retain stale information. Activation requires unmounting NFS clients, enabling the pNFS feature from the OneFS CLI, and restarting the NFS service, with a corresponding process to disable the feature.

Several configuration parameters control pNFS behavior, including a master enablement flag for advertising Metadata Server and Data Server capabilities, alignment settings that determine how file data is distributed across nodes, options for mapping network interfaces to pNFS devices, and internal settings governing layout tracking scalability. In particular, the stripe alignment configuration has a substantial impact on I/O distribution patterns and must be carefully considered when tuning performance, as different alignment values favor different workload characteristics.

Facet Details
Layout Layouts are per-file. Each time a client opens a file, it requests a layout that tells it which data server to use. Different files may be assigned to different nodes. How the client spreads its traffic also depends on the server settings around alignment.
Network SmartConnect determines the pool. The set of data server addresses returned to the client comes from the SmartConnect pool that the client’s mount IP belongs to.
Node roles Every node in the cluster acts as both a Metadata Server and a Data Server. The ‘MDS’ role simply means the node the client happened to connect to for that mount.
Protocol version Data I/O uses NFSv3. The pNFS Flexible File Layout standard allows data servers to speak NFSv3, which is well-supported and performant. The client uses NFSv4.1 only for metadata and layout management.

Every node in the cluster functions as both a Metadata Server (MDS) and a Data Server (DS), with the MDS role simply representing the node to which the client initially connects during the mount operation. Data I/O operations are performed using NFSv3, as permitted by the pNFS Flexible File Layout specification, while NFSv4.1 is used exclusively by the client for metadata handling and layout management. Layouts are granted on a per‑file basis, such that each time a file is opened, the client requests a layout identifying the appropriate data server, allowing different files to be serviced by different nodes, with overall traffic distribution further influenced by server‑side alignment configurations. The set of data server addresses provided to the client is determined by SmartConnect, with the addresses drawn from the SmartConnect pool associated with the client’s mount IP.

When it comes to enabling pNFS, ensure that the following prerequisites are met:

OneFS version OneFS 9.15 or later.
NFS protocol versions NFSv4.1 or NFSv4.2 must be enabled for the metadata path. Additionally, NFSv3 must also be enabled for the data path.
SmartConnect pool type The pool must use static IP allocation. Dynamic IP pools are not currently supported for pNFS because device addresses must remain stable.
Client OS Linux with kernel pNFS Flexible File Layout support (available in mainline Linux kernels 5.14+).
Client mount options The client must mount using either NFSv4.1 (-o vers=4.1) or NFSv4.2 (-o vers=4.2). Transport protocol may be RDMA (proto=rdma) or TCP (proto=tcp). UDP is unsupported.

OneFS pNFS support can be enabled via the CLI as follows:

  1. First, verify that the desired SmartConnect network pool is configured for static IPs:
# isi network pools list
  1. Next, check that NFSv3 and NFSv4.1 and/or NFSv4.2 are enabled:
# isi nfs settings global view
  1. When both the above prerequisites are confirmed, activate pNFS as follows:
# isi nfs settings global modify --pnfs-enabled 1
  1. Once done, the cluster’s NFS exports can then be mounted from a Linux client running kernel 5.14+. For example:
# mount -t nfs4 -o vers=4.1 <pool-ip>:/ifs/data /mnt/pnfs
  1. From the NFS client, after performing some I/O, the ‘mountstats’ file contents or CLI command can be used to verify pNFS is active. For example:
# grep -A 20 "pnfs" /proc/self/mountstats

Or:

# mountstats --nfs /mnt/pnfs

Specifically, the presence of non-zero ‘pNFS_read’ and ‘pNFS_write’ counters in the output confirms that the Linux client is using pNFS.

Optionally, as a second part to step 3 above, NIC-level device granularity configuration can also be applied. For example:

# isi_gconfig registry.Services.lwio.Parameters.Drivers.nfs.NFSV4LayoutDeviceUseNICAsUniqueDevice=1

Followed by an NFS service restart:

# isi services nfs disable && isi services nfs enable

Additionally, if pNFS does need to be disabled for any reason, first unmount any NFS clients, then run the following CLI command:

# isi nfs settings global modify --pnfs-enabled=true

The OneFS pNFS implementation (and the pNFS spec in general) does not require any changes to applications, as it is negotiated transparently between the NFS client and server. This allows applications to continue reading and writing files normally while the client kernel automatically manages layout negotiation and communication with data servers.

If a data server node becomes unavailable while a client holds a layout, the client may encounter I/O errors on the NFSv3 data path to that node. However, most Linux NFS clients will fall back to performing I/O through the metadata server (MDS) until the data server becomes available again, at which point they can re-request a layout, with the exact behavior varying by client kernel version and implementation.

OneFS pNFS is supported with both NFSv4.1 and NFSv4.2 and can coexist with non-pNFS clients on the same export, since pNFS is negotiated individually during session setup and clients that do not support it will continue using traditional NFS I/O paths while still accessing the same files.

Additionally, pNFS can work with RDMA when the server advertises both TCP and RDMA data server addresses and the environment includes RDMA-capable interfaces, enabling compatible clients to use RDMA for the data path.

Finally, pNFS requires NFSv3 to be enabled because the Flexible File Layout specification allows data servers to be accessed via NFSv3. The data path between clients and data server nodes uses NFSv3 for simplicity and compatibility, while the metadata operations, including layout management and file open or close operations, must use NFSv4.1 or NFSv4.2.